On August 4, Tencent Mix officially released a new generation of speech recognition model Hy ASR 3.0 preview. Based on the latest generation of major language model Hy3, Hy ASR 3.0 preview combines high-precision speech recognition with deep semantic understanding, achieving comprehensive improvements in core dimensions such as general recognition, up-context perception, multi-scene robustness, and dialect coverage, and is able to deliver accurate, coherent and closer to user intent transcripts in more complex real inputs, from word-for-word transcription, single-point optimization, to streamlined context understanding, to compatible scenarios, to single-key directing.
In the open-source assessment, the Hy ASR 3.0 preview controls around 3% of the multilingual WER (Word Error Rate, word error rate), including Chinese Mandarin WER 3.34%, English WER 2.62% and Chinese WER 3.12%, and the overall leading bid.
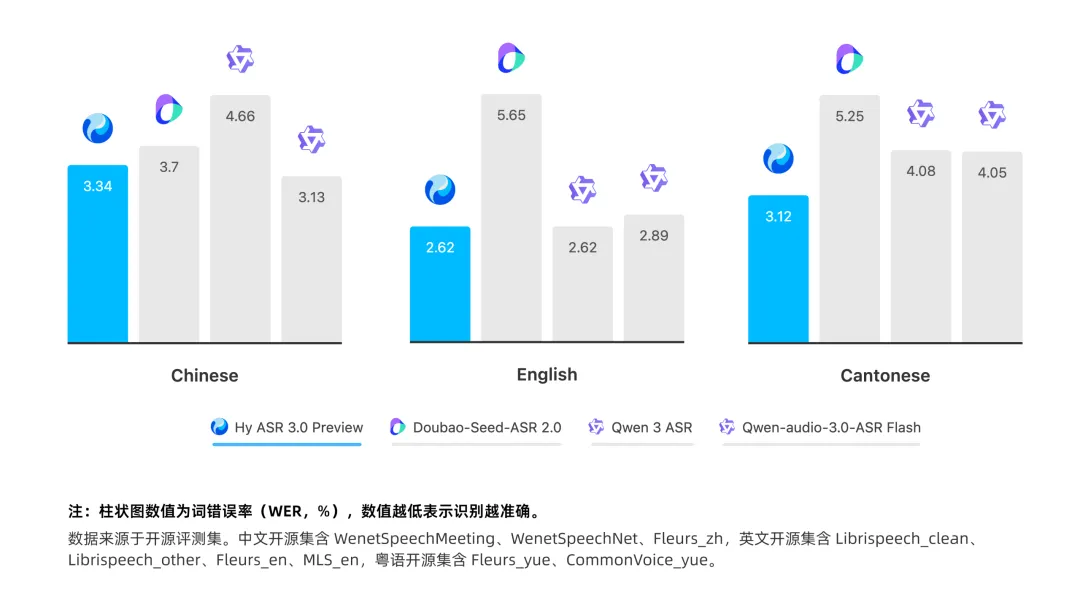
Open Source Assessment Set Performance: Hy ASR 3.0 preview achieves the lowest WER in both languages and dialects, leading overall performance
In the self-constructed assessment set, Hy ASR 3.0 preview in general recognition, language recognition, context understanding, vocabulary understanding, complex acoustic scenarios (high noise, noise) and other scenographic assessments, WER also maintains a lower level, leading the overall bid.
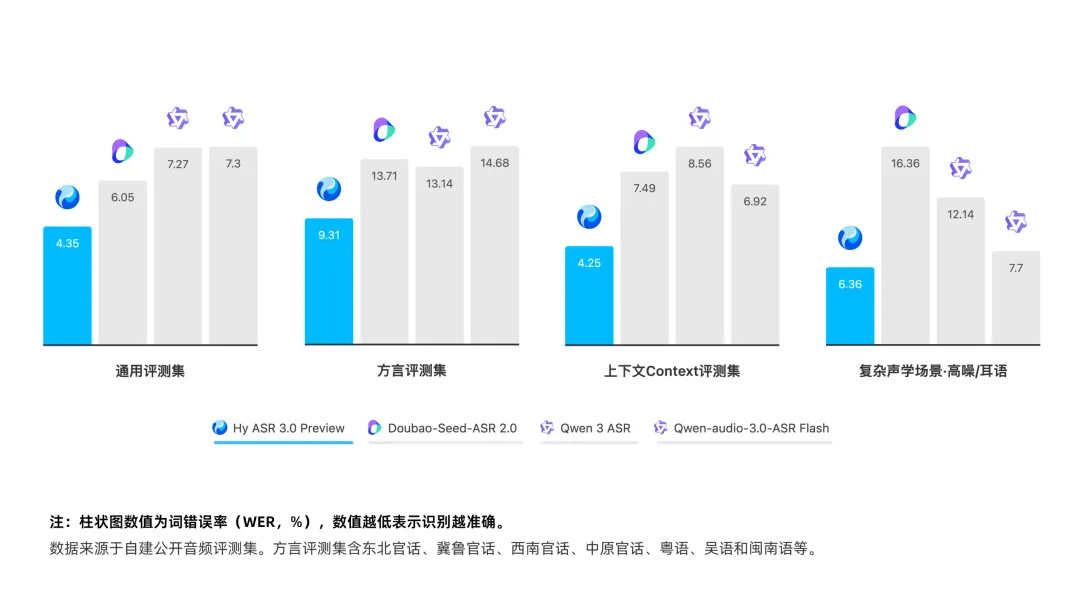
Performance of the self-assessment cluster: achieving the lowest WER on the integrated assessment cluster and leading overall performance
In terms of user usage, Hy ASR 3.0 preview focuses on improving four capabilities, including:
More accurate general recognition: improved recognition accuracy in general speech, dialects, and Chinese-English confusion scenarios, further reducing the accumulation of errors in misspellings, misspellings and long audio.
It is also able to understand user intentions: in conjunction with Context, accurately capture the context of the user, intelligently correct errors with vowels, and eliminate semantic ambiguity.
Easier to adapt to professional scenarios: Enhanced support for keyword insertion, helping models quickly identify brand name, brand name and industry terminology, reducing business access and ongoing maintenance costs.
It is more stable in complex environments: special optimization is carried out in a variety of acoustic scenarios, such as high noise, noise and noise, and it remains stable in complex conditions.
Continuous improvement in architecture, data and post-training to improve speech recognition limits
The enhanced capabilities of Hy ASR 3.0 preview do not come from a single module, but are the result of a collaboration between model architecture, data scaling and post-training optimization.
At the architectural level, Hy ASR 3.0 preview uses both efficient and performance MoE architecture and upgrades the baseline model to Hy3, further enhancing language understanding, context modeling, and semantic reasoning. On the voice side, the team develops an unsupervised voice encoder through tens of millions of hours of unsupervised voice data training that enables it to extract high-quality audio representations from complex audio.
In order to continuously improve the model's voice modeling and understanding capabilities, the mixing team jointly trained the voice encoder and the big language model, introducing tens of millions of hours of multi-source voice data, covering a variety of dialects, accents and acoustic environments, and fine-tuning labeling through high-quality data pipelines. Based on large-scale joint pre-training, Hy ASR 3.0 preview was injected with multi-stage capabilities to gradually gain context perception, complex scene adaptation and dialect recognition.
Based on general recognition, context understanding and complex scenarios, the team built a high-quality SFT recipe covering contextual contexts, professional nouns, different acoustic environments, and a variety of people's speech. For language recognition, the SFT data system further covers 10 major dialect regions and more than 20 secondary sub-regions.
On this basis, the team further introduced multi-stage reinforcement learning to optimize for general transcription accuracy, contextual capabilities on any-context, and complex long-tail scenarios, reducing the problem of model misidentification and leak recognition in complex acoustic environments.
Currently, Hy ASR 3.0 preview has been uploaded to Tencent Cloud to provide external API services, which can be widely applied to smart customer service, content understanding, voice search, etc. scenarios. Yuanbo is deeply involved in co-research and has completed its first upload, users open Yuanbo and press talk to experience dialect recognition, improve the ability to correct context-smart errors and stable transcription in complex environments, voice input more accurate, more stable, and open for free; products such as WorkBuddy are also in continuous access.
The following is a list of some of the most popular websites in the world.