「GPT is cooked.」
Over the past two days, the phrase has been repeated in the AI community. The image model MiniMax H3 Image has just been released.
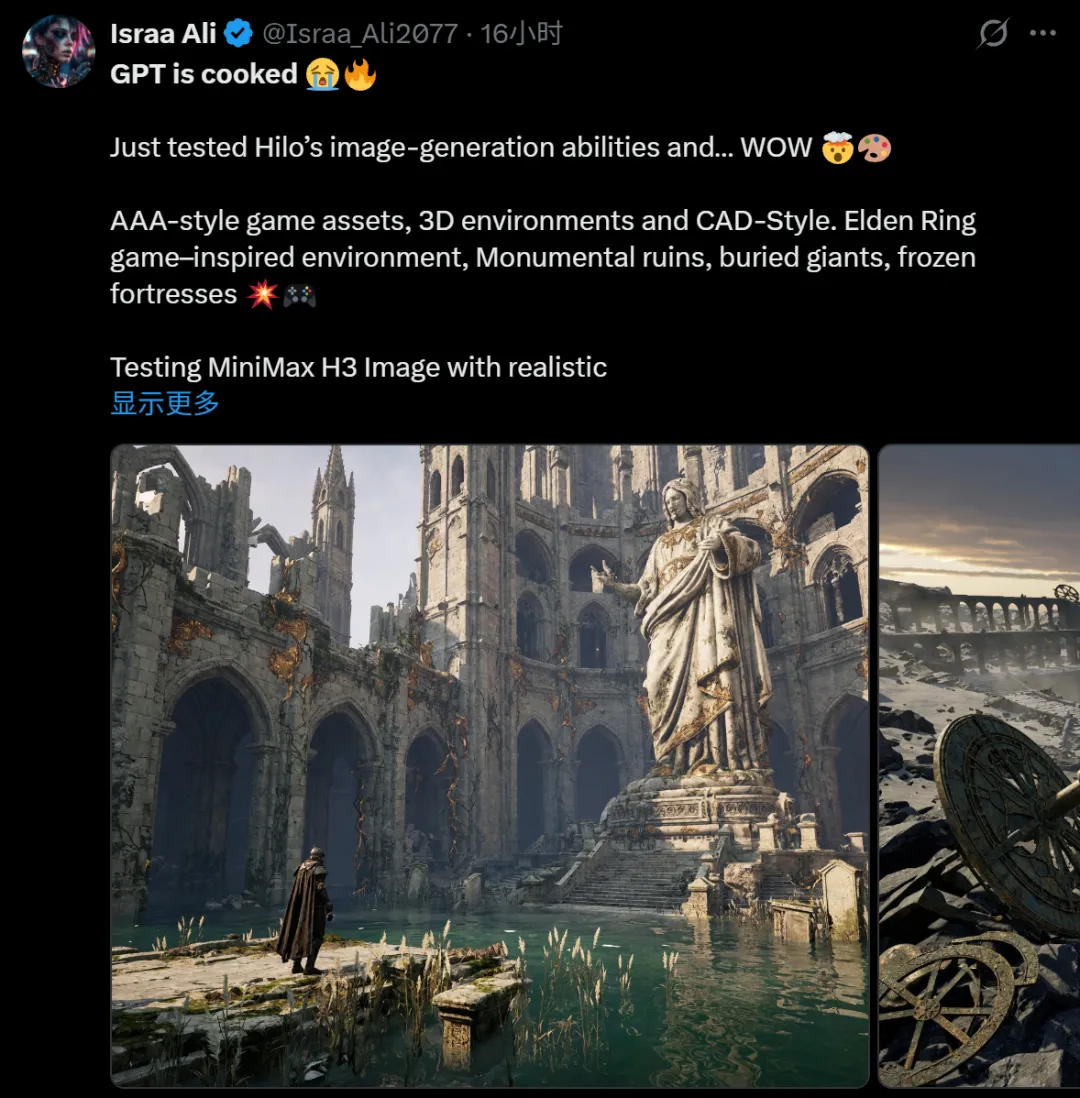
This is a native 4K straight-out, 10-second generated model that supports 16 reference charts, just open-source this Tuesday, refreshing the SOTA open-source image model.
Numerous tests were carried out by developers with in-person measurement privileges. In the new model's output, AI people like the "plastic skin" is missing, holes, sparrows, sweat hairs are clearly visible. People praised its ability in game design, character setup and 3D scenes.
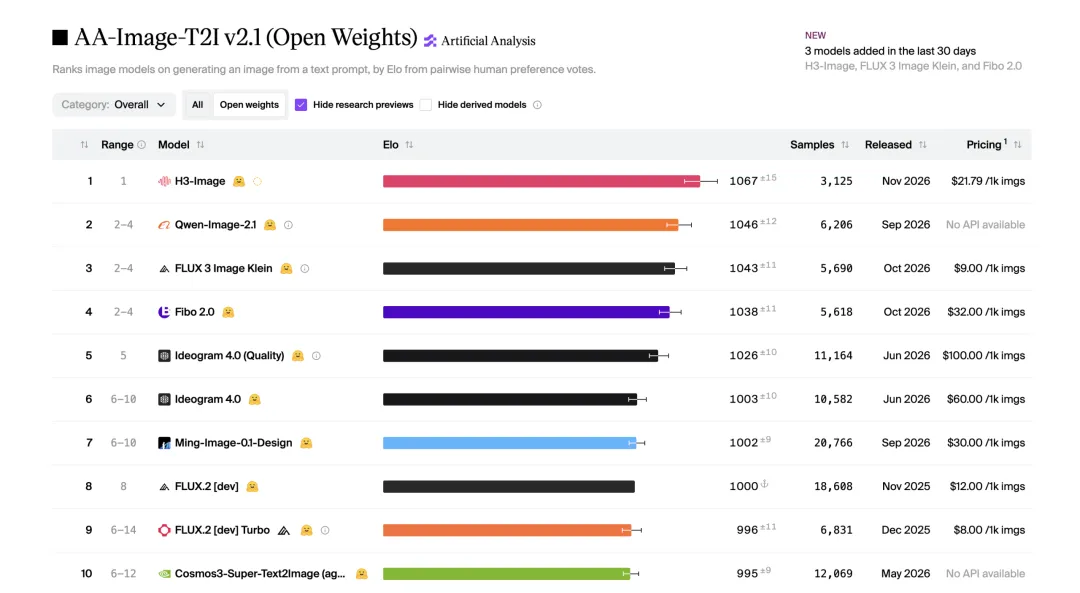
In today's updated Artificial Analysis list, MiniMax H3-Image is ranked first in both lists of open-weight models in text graphics and image editing.
MiniMax H3 Image supports direct use at the end of the web, and can be used through an API in MiniMax Code or other harnesses to complete complex tasks. It is open-source and is already being deployed locally.
GitHub:
HuggingFace:
This is the first time we've gotten permission to use the new model to help you see what level of testing it is.
Re-defining visual aesthetics with "reality"
The new model is now available in MiniMax Code, which opens to support up to 16 reference charts and generates images with up to 4K resolution.
From the point of view of ordinary users, we measure the scenes we use on a daily basis in four dimensions of ability, first we look at the reality, then we look at the two classic puzzles of words and faces, and finally we try to create a second picture.
The real effect is the first link. The most easily exposed traces of AI are often what we see every day, such as the WeChat chat interface.
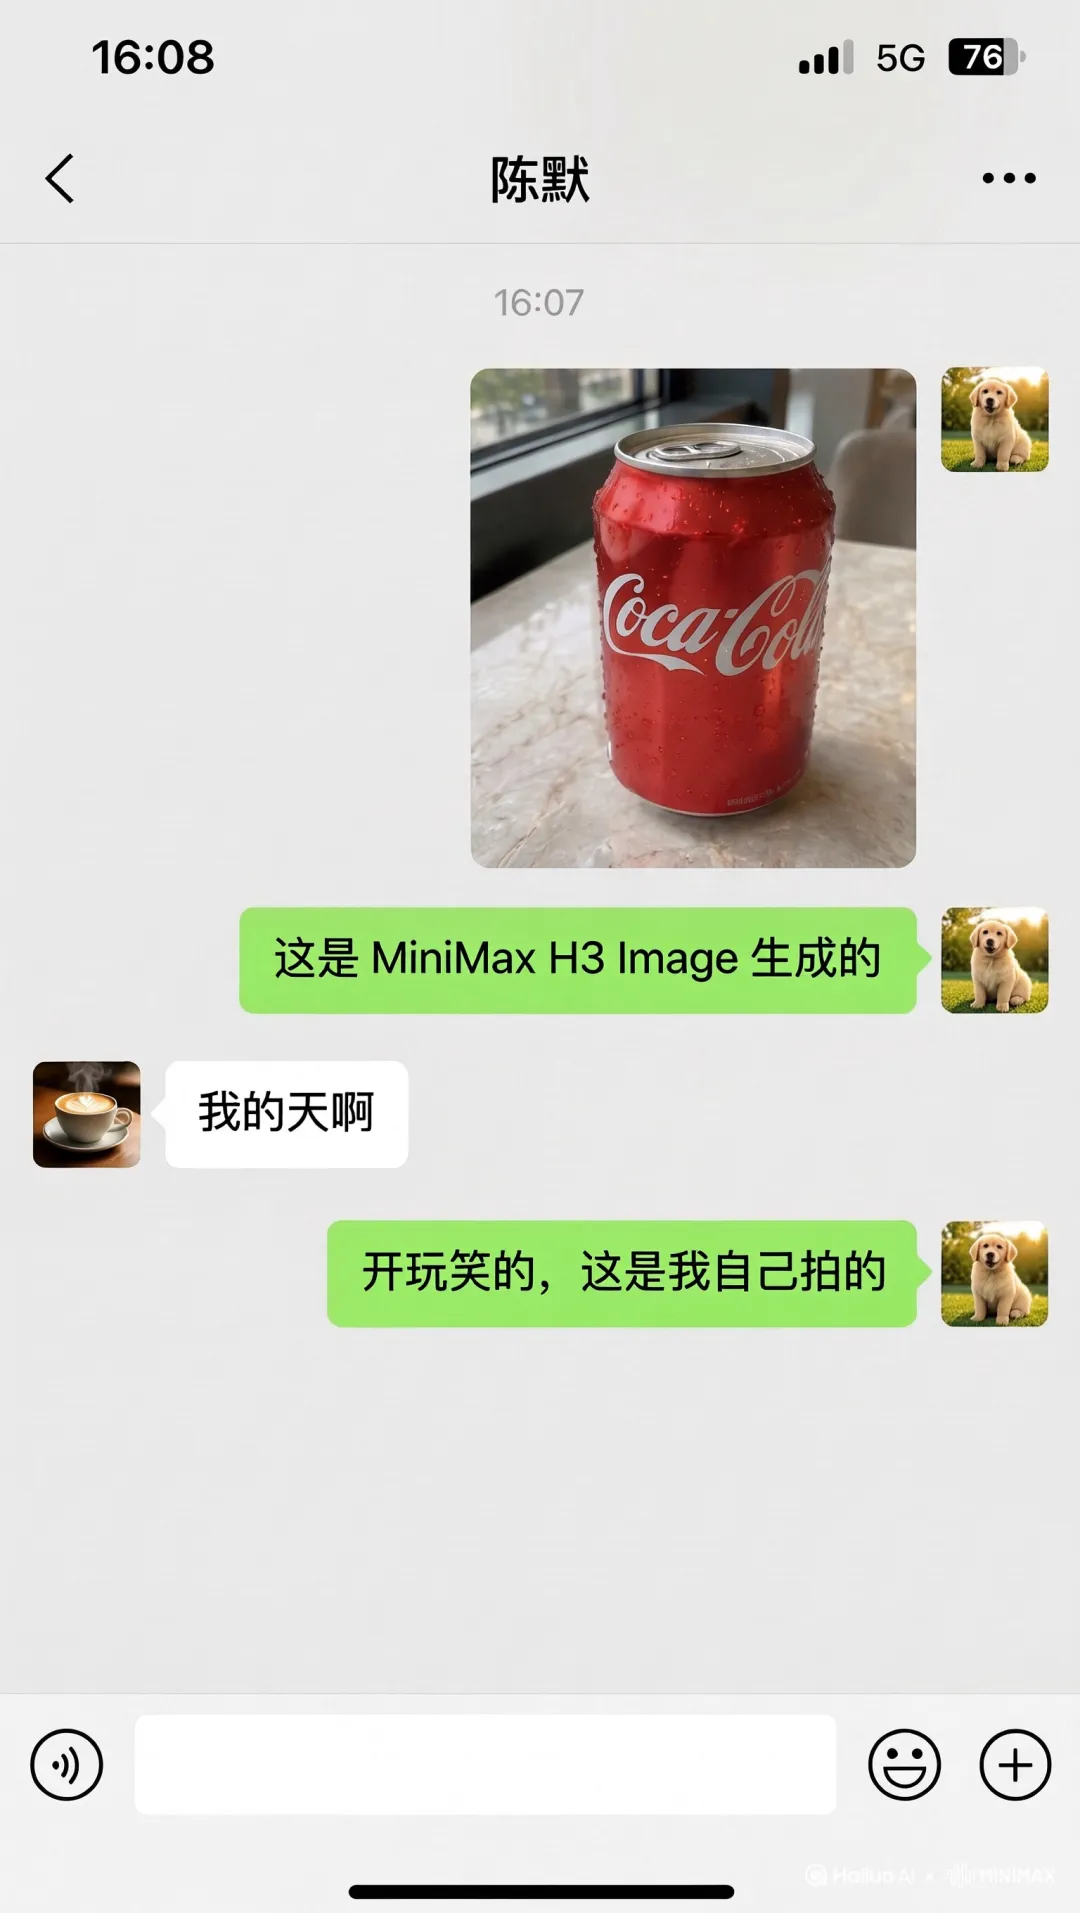
Tip: Generate a WeChat chat snapshot: I send the person a very realistic photo of Coca-Cola and say, "Hey, this is the chip from the MiniMax H3 Image", and the person replies, "Oh my God, hey, hey", and then I say, "That's a joke, this is my own chip. Please make sure the snapshot contains highly realistic iPhone status details, including time, battery power, and signal strength".
The MiniMax H3 Image generates a complete WeChat chat screenshot.
This type of everyday interface is difficult because the human eye has a very low error tolerance for familiar scenes. WeChat interfaces have relatively fixed visual specifications, are slightly rough in type, chat bubble spacing is slightly different, or the status symbol proportions are incorrect, and are instantly recognizable.
In many models, when generating similar chat shots, either the interface elements are distorted, or product photos appear in unnaturally high light, which is a real discount.
While the MiniMax H3 Image produced the iPhone's state-of-the-art design, WeChat UI layout, chat bubbles, headshots, and details are all in place; Coca-Cola photos are also realistic enough, bottled water, photo reflection, and desktop texture are all natural, with almost no trace of AI.
What follows is the old problem of the Graphics model, which is the rendering of text. The previous model was not a spelling error, it was a spelling failure, and this time we directly gave H3 Image a complicated graffiti:
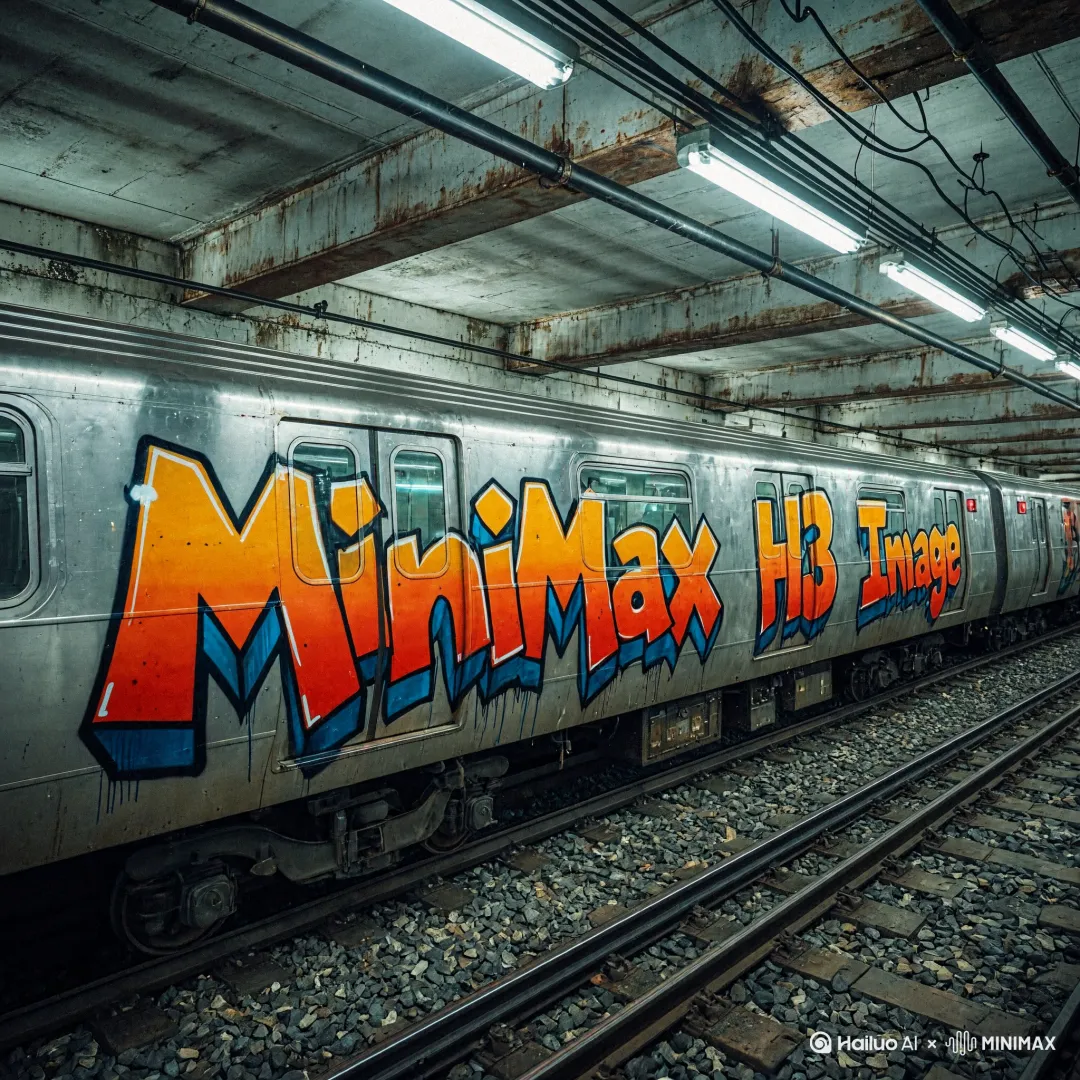
Note: This is a realistic-style graph, with a row of silver stainless steel underground carriages with years' traces parked inside a rough underground station. The side of the carriage is covered by a huge wild-style graffiti that spans the entire driveway window. The graffiti is composed of 3D triangular block letters that are distinguished by corners, spelling out the MiniMax H3 Image graffiti; the inside of the letter is filled with bright orange and has progressive effects, accompanied by deep blue 3D projections, rough black lines and fine white lines that can even be seen underneath fresh spray paint. In the background, the dark industrial corners of the sky are exposed to the outside, mimicking the effects of steel wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire wire.
The "MiniMax H3 Image" is a long string of letters that not only spells out the full text, but also creates a three-dimensional shaping, gradual filling, and painting effect.
People's photographs come up with a big feel, but the test is not just about the colors, the carvings, the details of the clothes and the atmosphere of the photos.
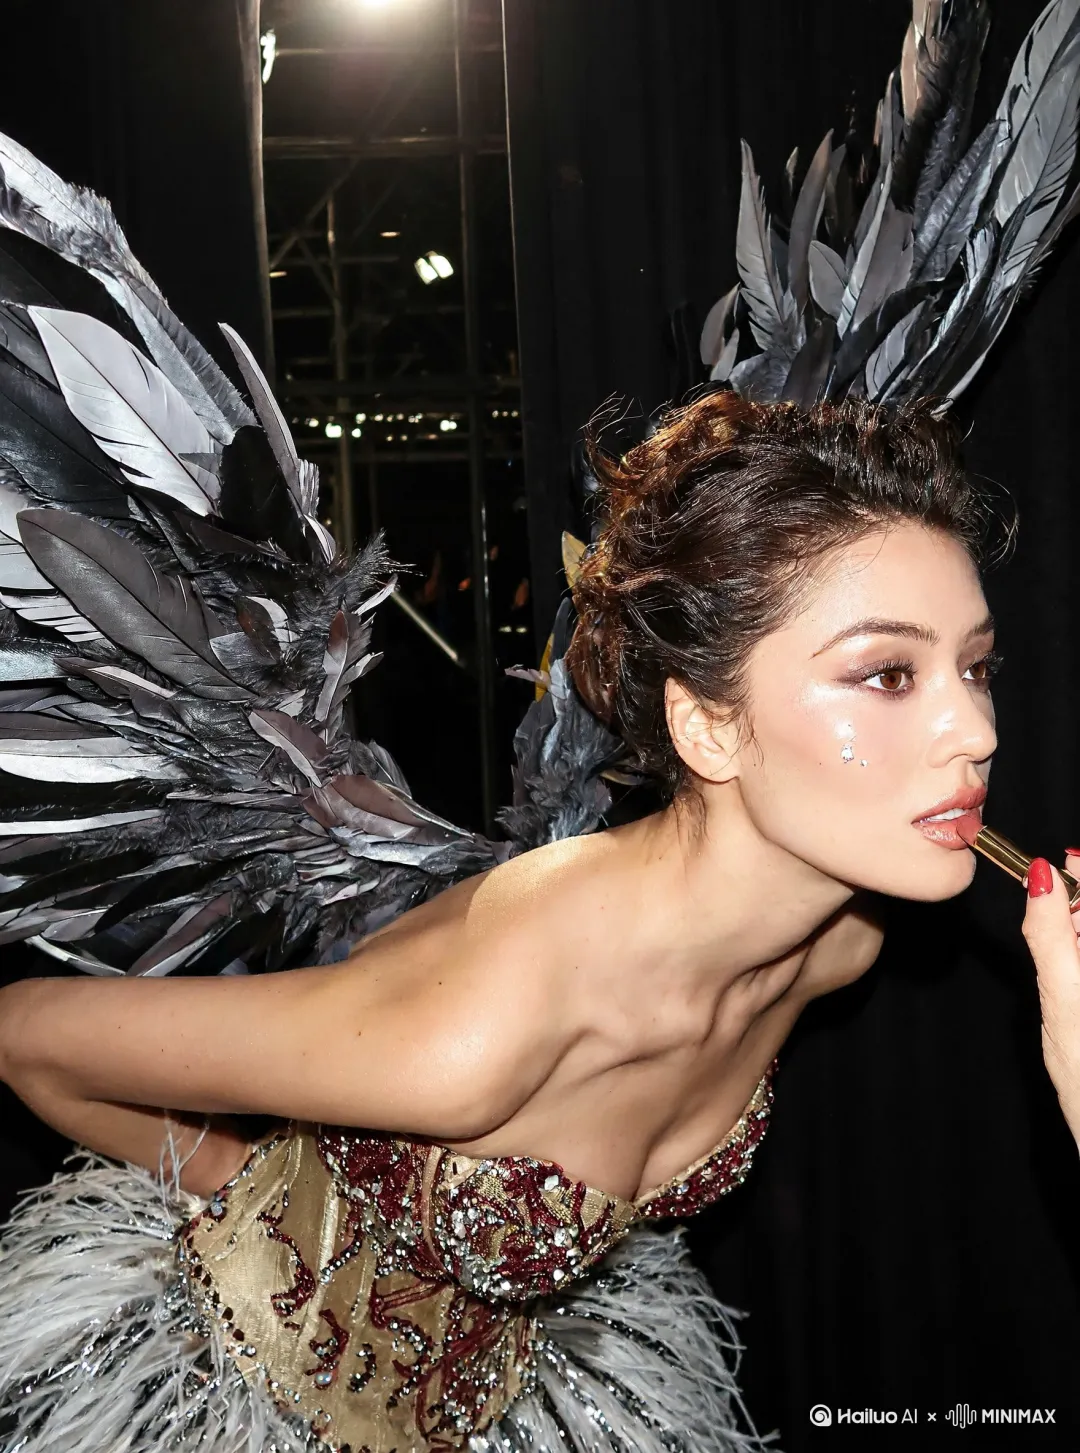
It's a good idea. A young woman attached in the uploaded reference image (Keep the face of the person 100% accurate from the reference image) stands almost sideways, slightly bent forward, during the final preparation for the show. Makeup artists apply lipstick to her (only her hands are visible in the frame). The background is a darkly lit room, probably under the podium. The main emphasis is on the girl's face and the details of her costume. Emphasize the expressiveness of the gaze and the luxurious look of the outfit. Victoria's Secret style: sensuality, luxury, glamour. Very detailed. Important: do not change the face.
Complex elements such as crystal jewelry, feathered wings, and other details are blinking, and the model's skin gloss and clothing reflectance levels are clearly visible.
It's a different style, try a movie sensation:
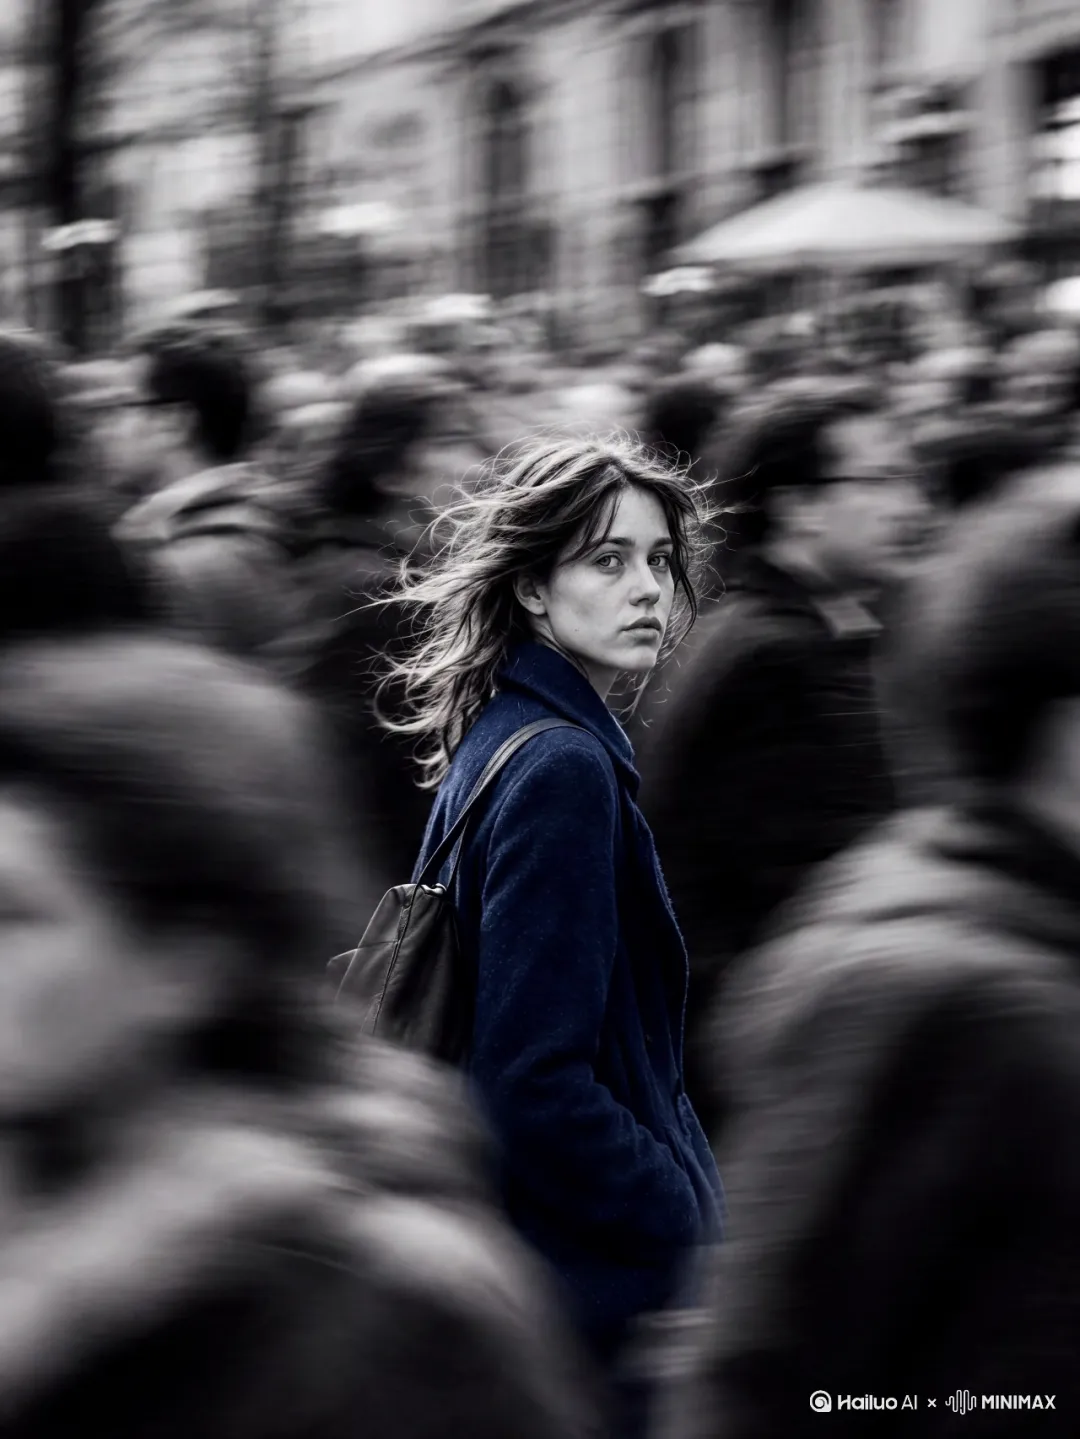
The street is very much like a film shot, the moments of feedback are clearly categorized, and the pedestrians around are treated as dynamic drag shadows, and the whole atmosphere, sensations and emotions are all online.
We also unlocked Millennium Retrospectives.
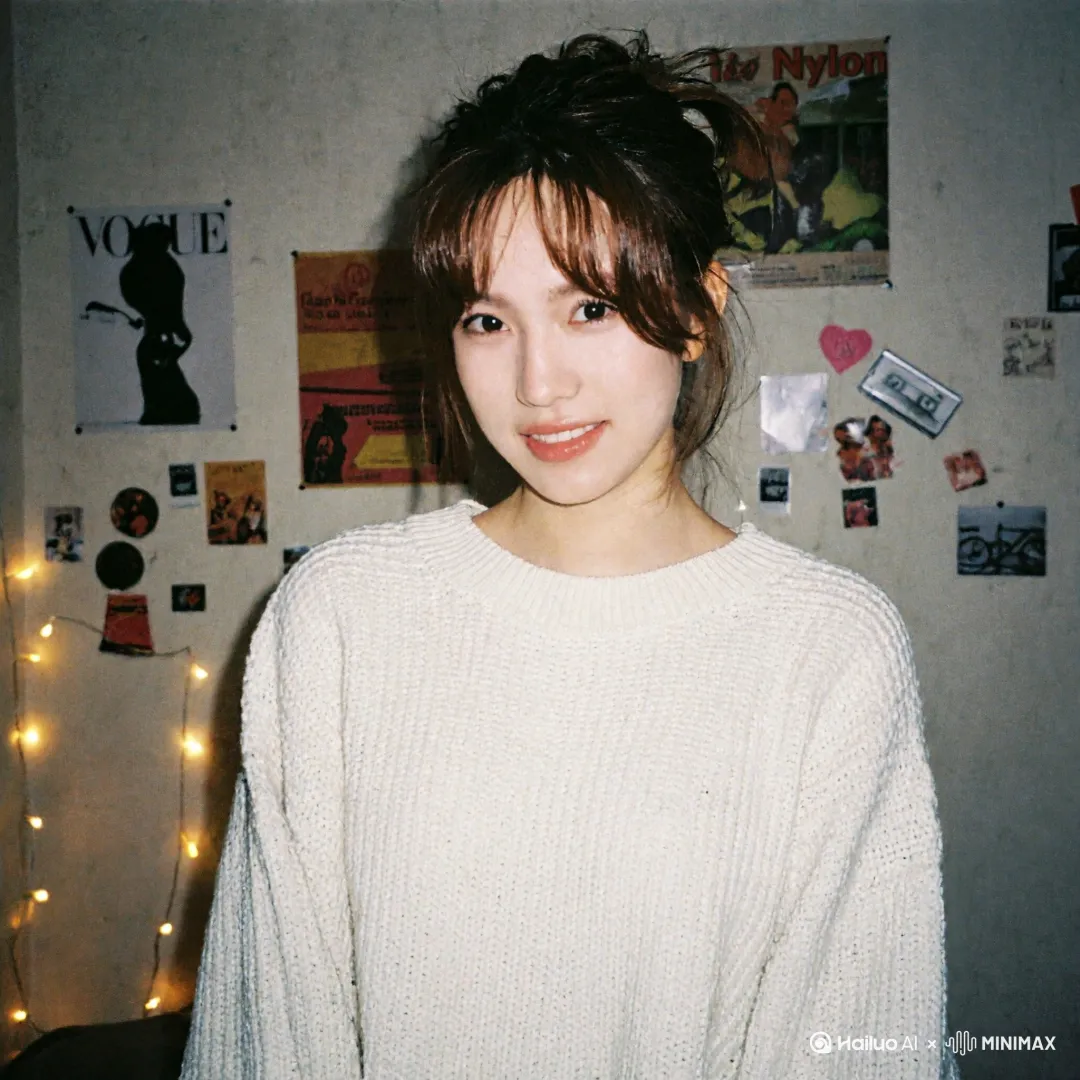
It's a good idea. Without changing her original face, create a portrait of a beautiful young woman with porcelain-white skin, captured with a 1990s-style camera using a direct front flash. Her messy dark brown hair is tied up, posing with a calm yet playful smile. She wears a modern oversized cream sweater. The 35mm lens flash creates a nostalgic glow.
With a slightly noisy film texture, old magazine posters on the walls, warm yellow strings, let's go back to the 2000s, and a slightly over-exposed and very old-fashioned digital camera feel.
This section requires AI models to understand the original diagram and modify it as instructed.
First, Namask uploaded a picture of him, and the model turned him into an ugly, hand-painted WeChat face bag, the character's original ideology was exaggerated, combined with a twisted, twisted "So Dumb", sweat drops and a question mark, and a face bag that could be taken directly from the drawing was fine.
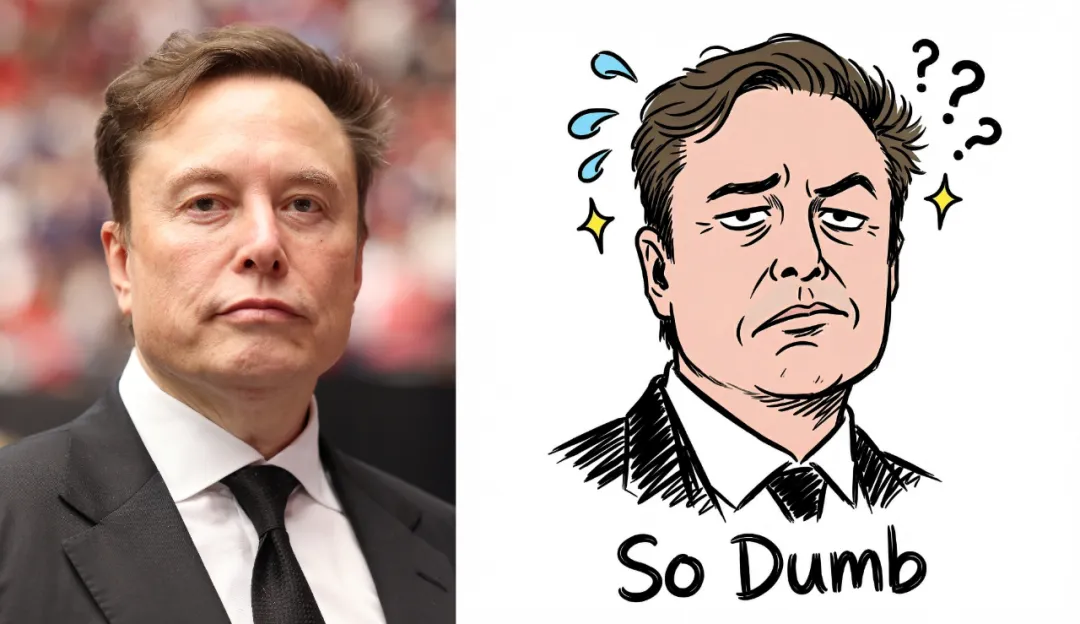
Tip: Draw it in a funny hand-drawn micro-facial. Using a very short, ugly line drawing with a touch of hand-graffiti, the background is pure white. Depending on the characters in the original photo, it looks shocked, disliked or exaggerated. Add a few drops of sweat gems, question marks or glittering stars around the head.
The next round adds to the difficulty. Uploading a CCTV surveillance photo of a street requires the model to identify the person in the image, adding a white person's face frame one by one, and generating high-resolution magnification for the most prominent person.
The resulting scene layout and monitoring perspective of the original image are preserved, while the main image maintains the appropriate noise and slight distortion, while the faces in the enlarged frames are clearer and look much like the analytical images produced by the monitoring system automatically.
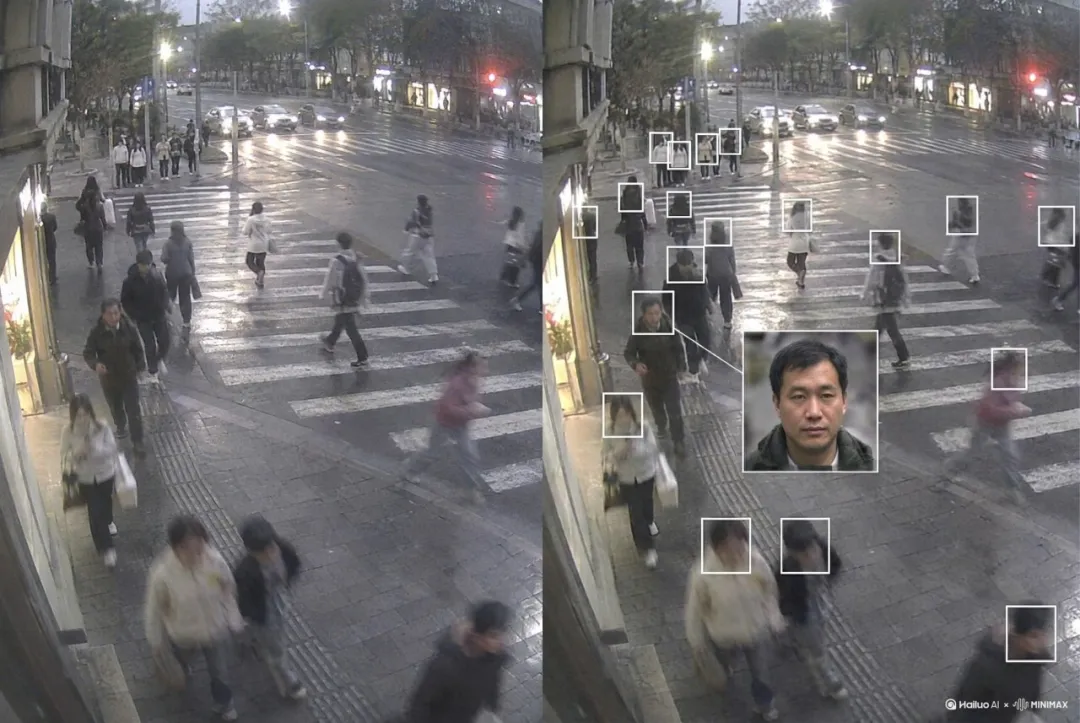
It's a good idea. Create a high angle CCTV surveillance shot using the uploaded image as the source. Detect every visible person in the image and automatically draw a white rectangular bounding box around each face. For the most prominent person, add a large zoom in inset: a sharp, enhanced close-up of their face displayed in a floating rectangular frame connected with a thin white line.Keep the main image slightly noisy and security. camera like (soft grain, slight distortion, muted colors), while the zoom in face box should be clearer, brighter, and more detailed. No text, no timestamps, no overlays except the boxes and connecting line. Maintain the original scene layout, angle, and environment of the uploaded image.
If you want to turn a painting into a real style, we turn it into a two-dimensional collage style:
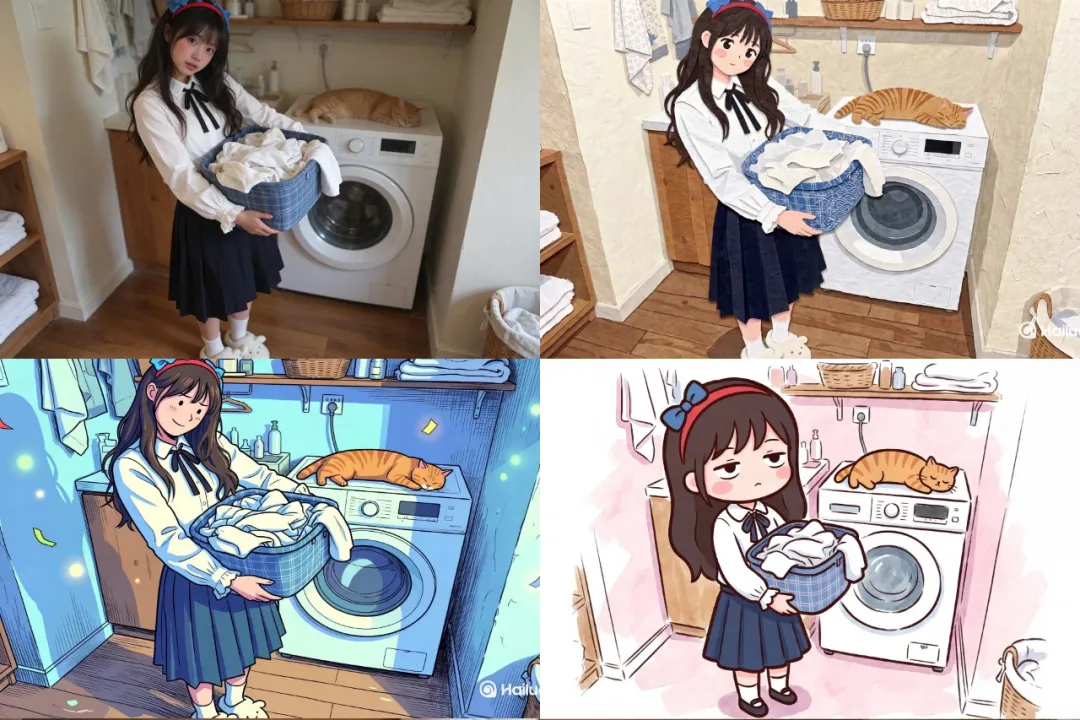
It seems to have worked very well.
As you can see, the MiniMax H3 Image can both generate photo-level maps, help you realize some creative ideas, and allow you to participate in the battle, this time the effect looks better than before, the reality is full, and the taste of AI has become very faint. It is also worth mentioning that its instructions follow the ability to understand and produce the right results in the face of the complex information we are given.
This means that we should not expect it to be functional.
Understanding and Following Directions of the Physical World
Much of the above is the reality of AI producing images, and below we're going to look at something more rigid: whether the model really "understands" what it's painting, which is very important for some actual design work.
In this respect, the model must have a correct understanding of the structure and material of the physical world, be clearly organized when information points are dense, and be able to adjust precisely according to instructions.
The key here is not only aesthetics, but the model must also have knowledge of the physical structure of the camera, what parts it is made of, how it is embedded between the parts, and where the location of its space after disassembly is often exposed.
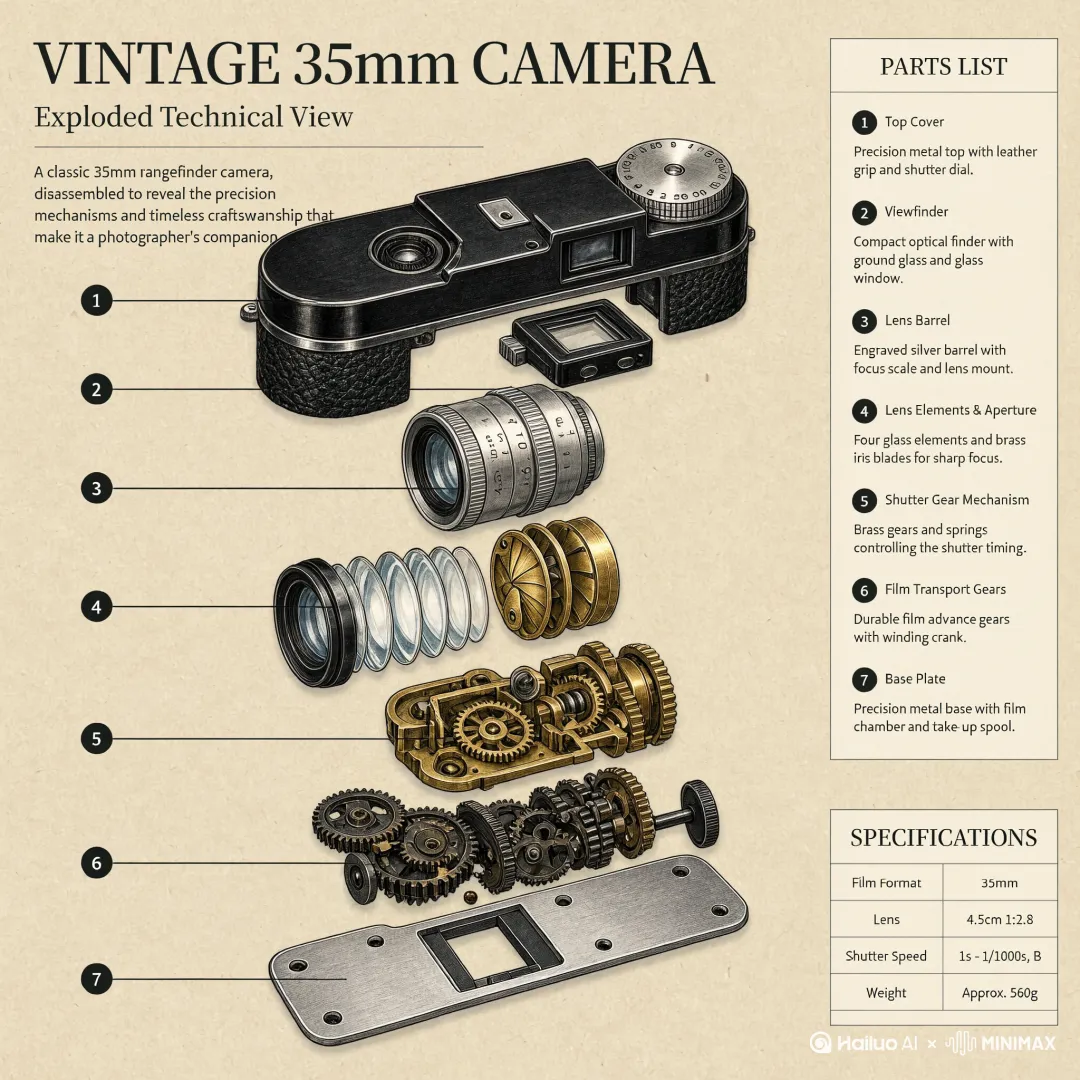
A classic 35mm side-axis camera with an explosive breakdown view, 16:9 side-by-side edition, warm creamy-white background. Seven camera parts hang vertically along the center axis, accurately aligned, layered with white: a black stripe leather and a metal rotating top, a small viewer, an inscribed silver lens cylinder, a four-piece glass lens with a bronze light circle component, a bronze fast shutter mechanism, a deep shutter transmission gear assembly and a shake metal panel. Fine-technical illustration style, fine steel pen linings combine soft writing and real rendering, rubber metal, polished brass, penetrating glass, leather texture texture authenticity, soft projection, low chrome and retro colours, clean engineering manual aesthetics, flattened information graphic design, high resolution.
It is possible to see the body, lens, gear and other parts of the image that it generates disassembled in layers, and the number labels, English instructions and parametric tables are also generated at the same time, almost at the level of the product manual.
H3 Image can generate highly accurate real-life clothing photos, and fashion bloggers' meals can also be "robbed".
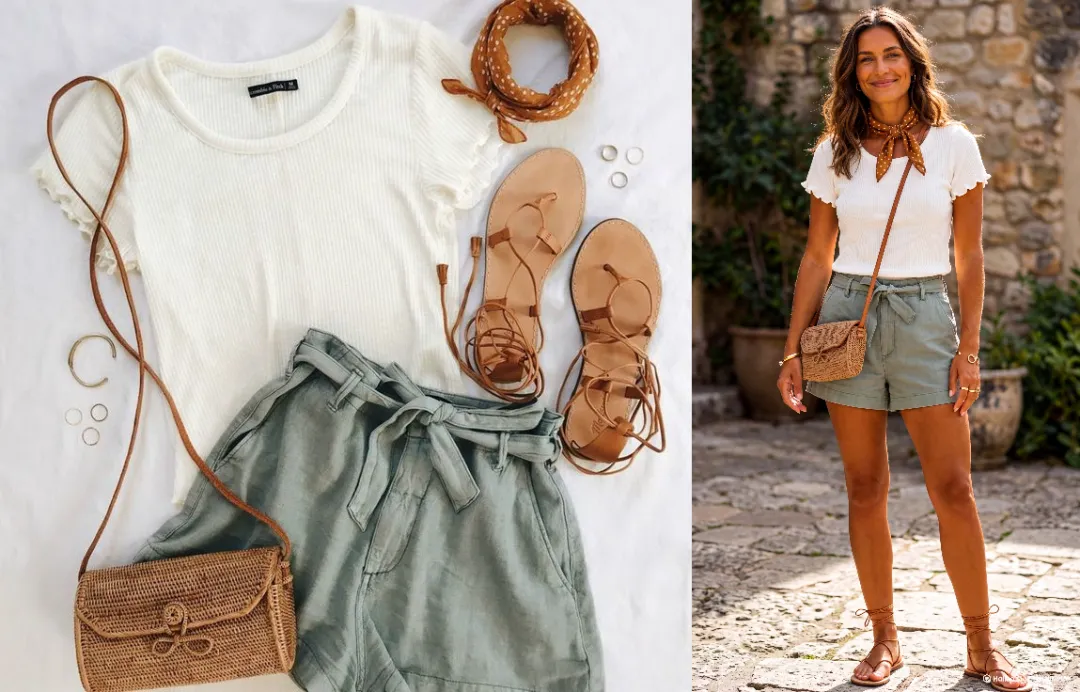
Show the woman wearing the outfit.
E-commerce is one of the most ground-breaking scenarios for creating AI images.
Nowadays, many merchants have begun using AI to create product headlines, detailed pages and marketing posters, but the real test of the model is whether it can accommodate the quality of the product, brand information and visual composition at the same time, so that different elements do not collide in the same image.
The material produced, the subject matter of the commodity, the material, the packaging and the details can be enlarged, and the surrounding decorative elements also evoke the point of sale of the product. In a multi-layered word sequence, a clear visual layer is formed between the brand title, product name and promotional information.
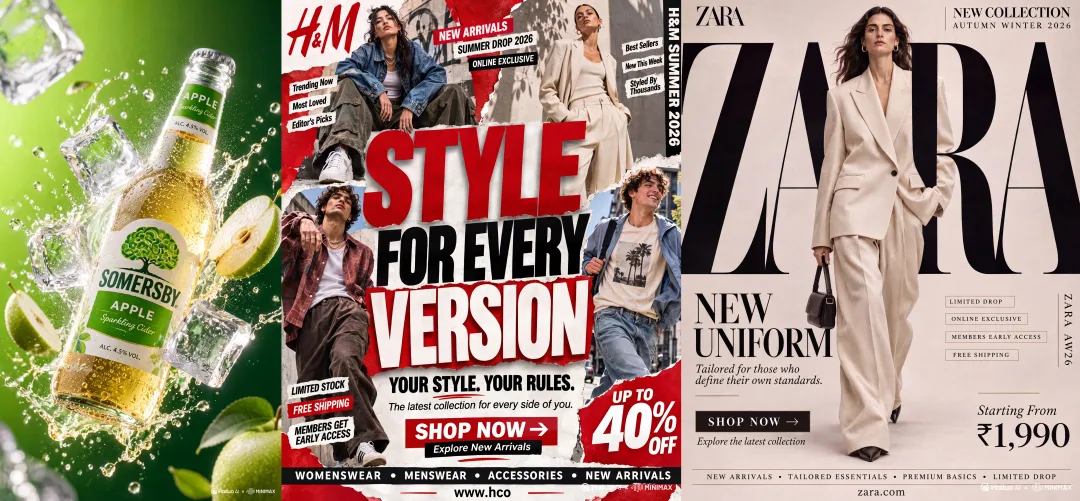
In terms of graphic design, what we want is not only aesthetics, but also the accuracy of the wording of the poster, a hint word in a dozen information points would not be wrong?
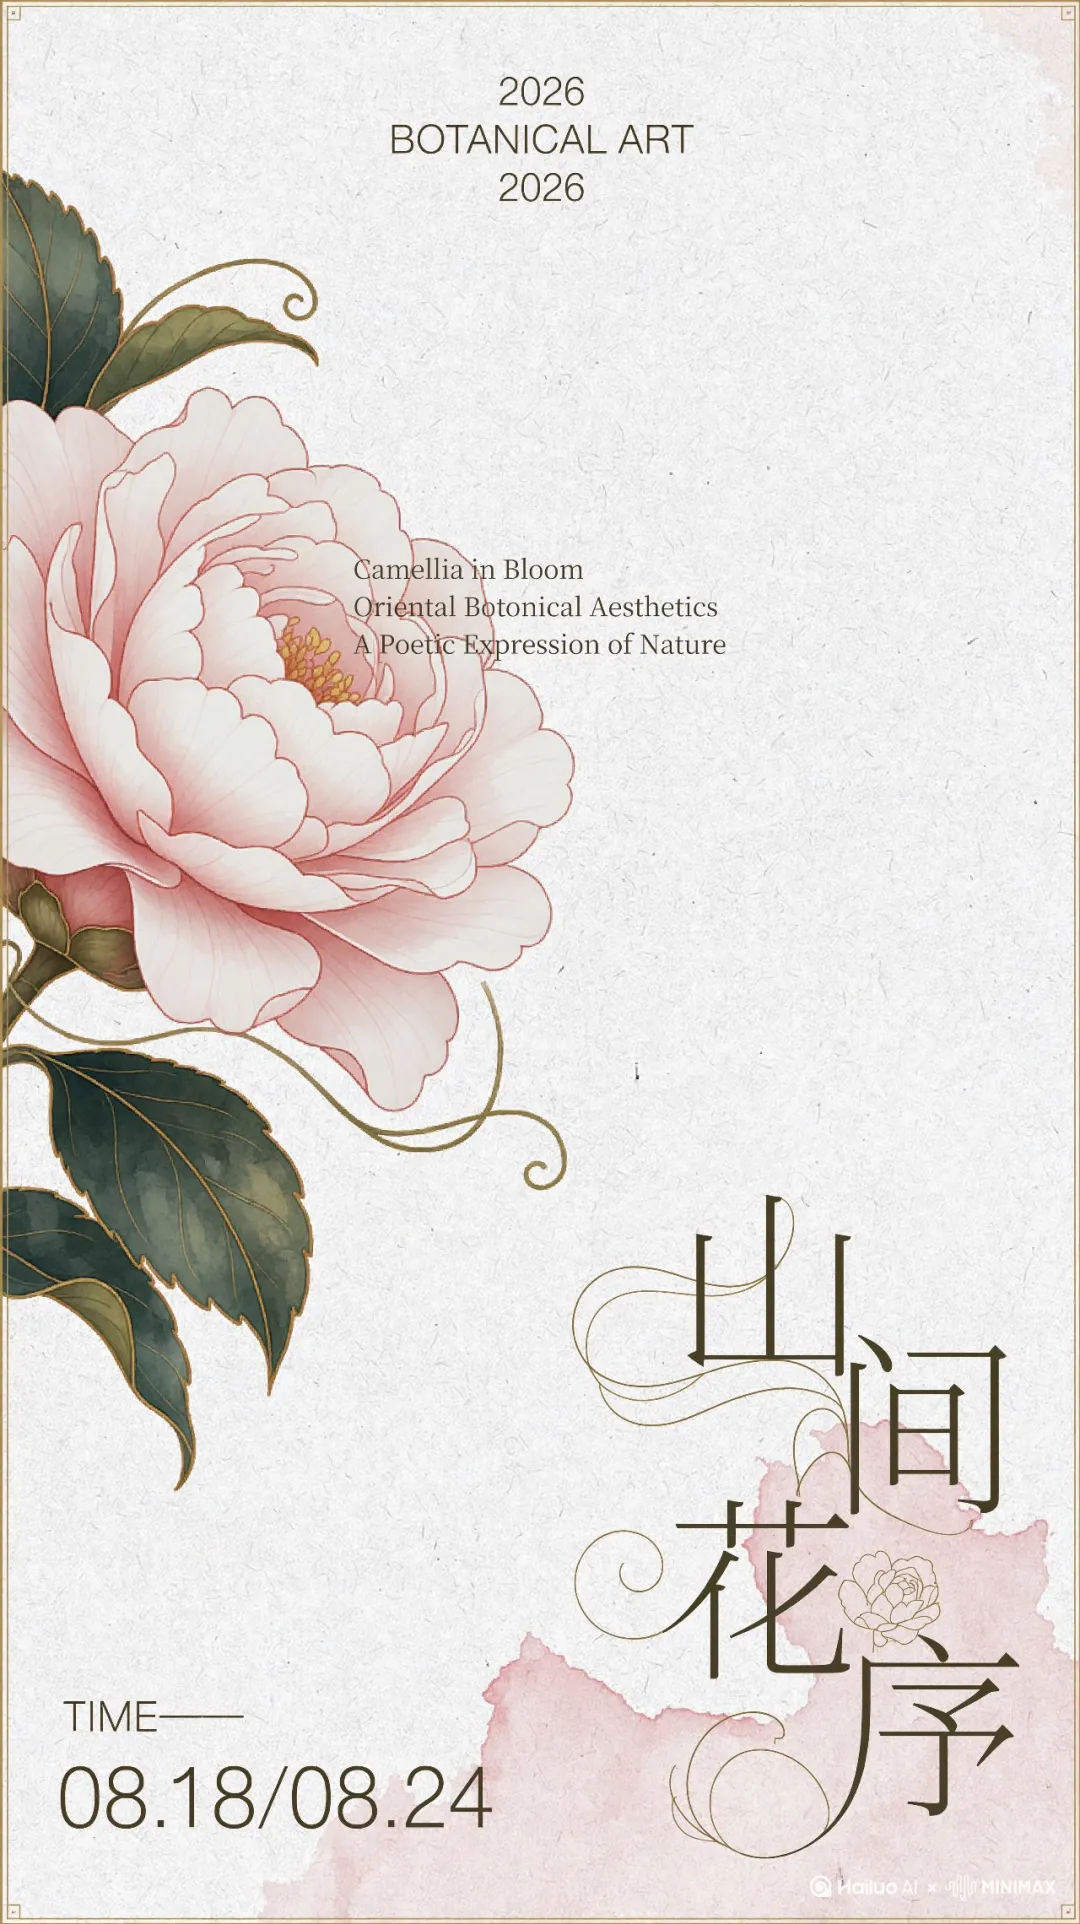
Suggestions: Extreme classical aesthetics, high-quality posters, oriental mountain tea flower art, fine floral textures, white to light pink gradient effects, artistic conceptual style, visual clarity and full of oriental classical feeling; subtitles in the lower right corner of the image: subtitles for type design, ultra-thin body style, "mountain sequences, tail patterns, tail patterns, tail patterns, tail length, pencil section adding body curves, natural insertion in between the letters, the whole presents eastern poetry, exploring the artistic expression of the natural flowering and microscopic plant world; subtitles at the top of the image are "2026" BOTANICAL ART" "2026", and subtitles at the bottom left are "TIME 24/08.
Finally, check out H3 Image's ability to follow instructions. For many people, the most commonly used scenes in their daily work are image editing, adding, deleting, modifying, replacing, almost basically, with clear semantic operations.
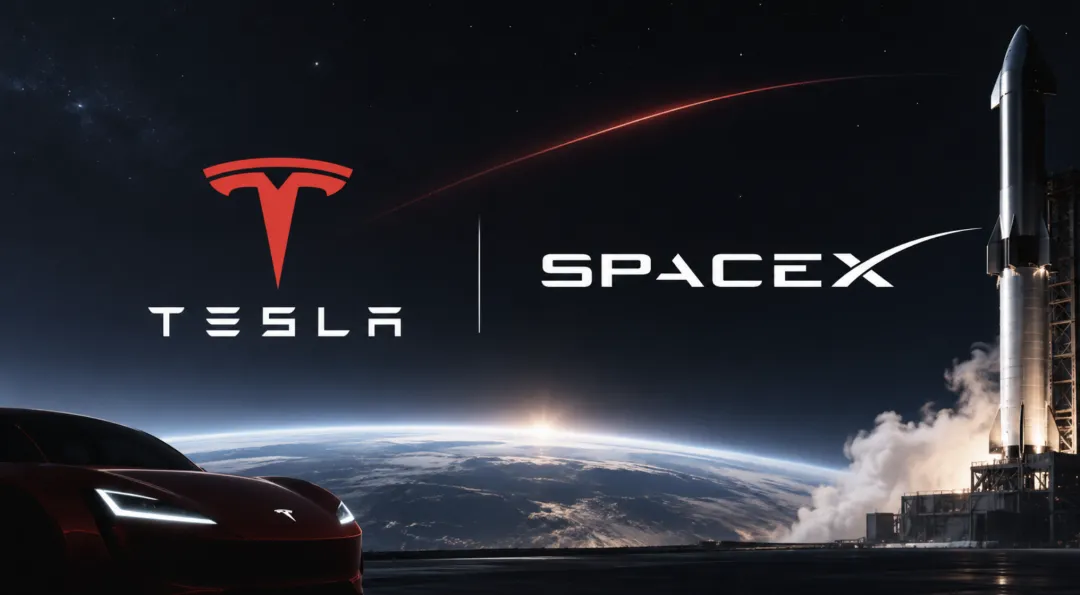
Think about it, it's almost as if Musk's announcement of the "opportunity to recruit Huang Ren" means "it's an honor". Let's think about this scene: Huang was greeted with a Sink at SpaceX's doorstep, and it took a series of instructions to generate this image, along with a few reference images:
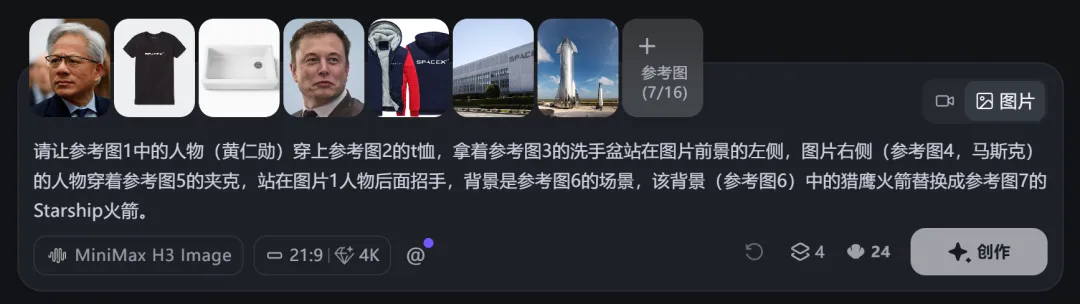
That's how fast the fire started.
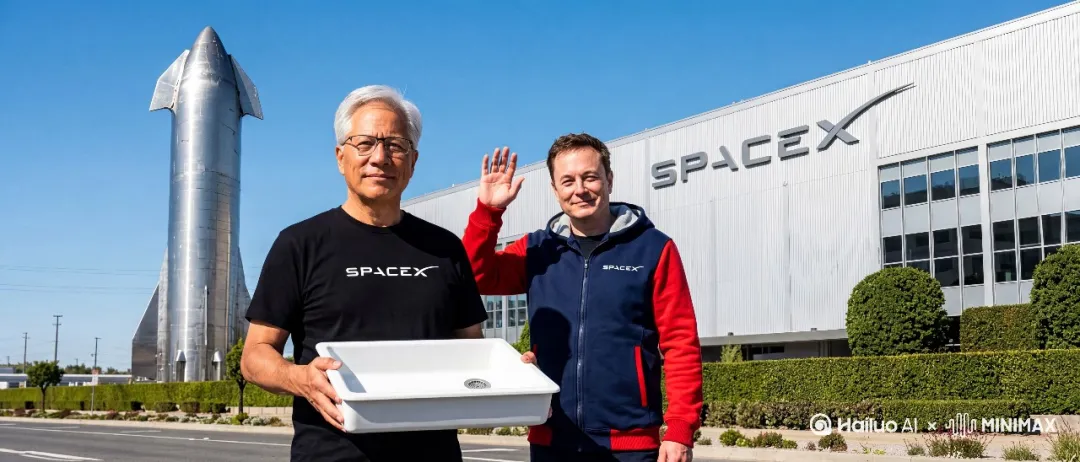
At the aesthetic level, H3 Image is capable of stable output-level photographic authenticity, facial retention, style transformation, and a sense of detail; at the productivity level, the completeness of word ordering, local editing, e-commerce posters, and industrial graphics is sufficient to support the workflow. From everyday use to professional production, open-source AI image models have reached the range available.
After seeing the test results, we started to wonder what kind of model the MiniMax H3 Image was.
Video models
How did you become SOTA?
Unlike most bioimages on the market, H3 Image is a derivative of MiniMax's full-mode video model H3, which was released in late July and is an open-weighted general-purpose full-mode generation system in which text, images, video, and audio are unified into the same architecture to generate native stereo video.
H3 Image follows the overall design of H3-Base, removing the audio branches and retaining architectures such as the backbone network, text encoder, and the text side, which directly uses H3, a 32-billion-parameter multi-modal language model responsible for understanding complex instructions, long descriptions, and multi-conditional logic; on the image side, the reference graph enters two modules simultaneously: the text encoder is responsible for understanding "what's in this chart, and the image VAE" is responsible for compressing the element into a visual potential variable that can be processed by the generating model.
The following is the core of H3 Image: a 3.31 billion-parameter distributed Transformer (DiT) encoded along the same three-dimensional model rotational positioning as the H3 Omni Transformer. Text tokens, reference graphics tokens, are packaged into a complete sequence to penetrate the network in a single stream, directly predicting the potential variables of the target image, and finally decoding the graphics by VAE.
In terms of resolution, H3 Image chose to go straight ahead without installing any oversized modules, and a checkpoint directly generated about 16 million pixels of images, covering a variety of proportions from 4096×4096 to 21:9 of 6272×2688.
H3 Image also has a fast mapping speed: the P50 medium takes about 10.3 seconds, the high-speed version is about 16 seconds, and the peer-to-peer comparison model generally takes about 50 seconds.
MiniMax goes back and forth from the video model to the path of the image model, and the traditional graphic priority path is the opposite. In fact, this has many advantages for image generation, after all, in order to maintain the coordination of continuous images, the video model needs to learn the different perspectives of objects, the material changes when exposed to light, and the movement of the person, body and object.
It is no wonder that MiniMax H3 already has a rich knowledge of the visual world and produces a good H3 Image as its basis.
Global AI ecosystem
Relying on open sources
With the rapid development of AI technology and the sudden emergence of new model capabilities, it doesn't seem like it's always going to be "shocking".
Today, MiniMax has launched a new model that is already a big deal for the AI circle, and this enthusiasm has long been transformed into an ecological boom. MiniMax is moving from a company that provides AI models to a platform for other AI startups to develop technology.
In fact, before H3 Image, an image generation model called P-H3-Image appeared overseas.
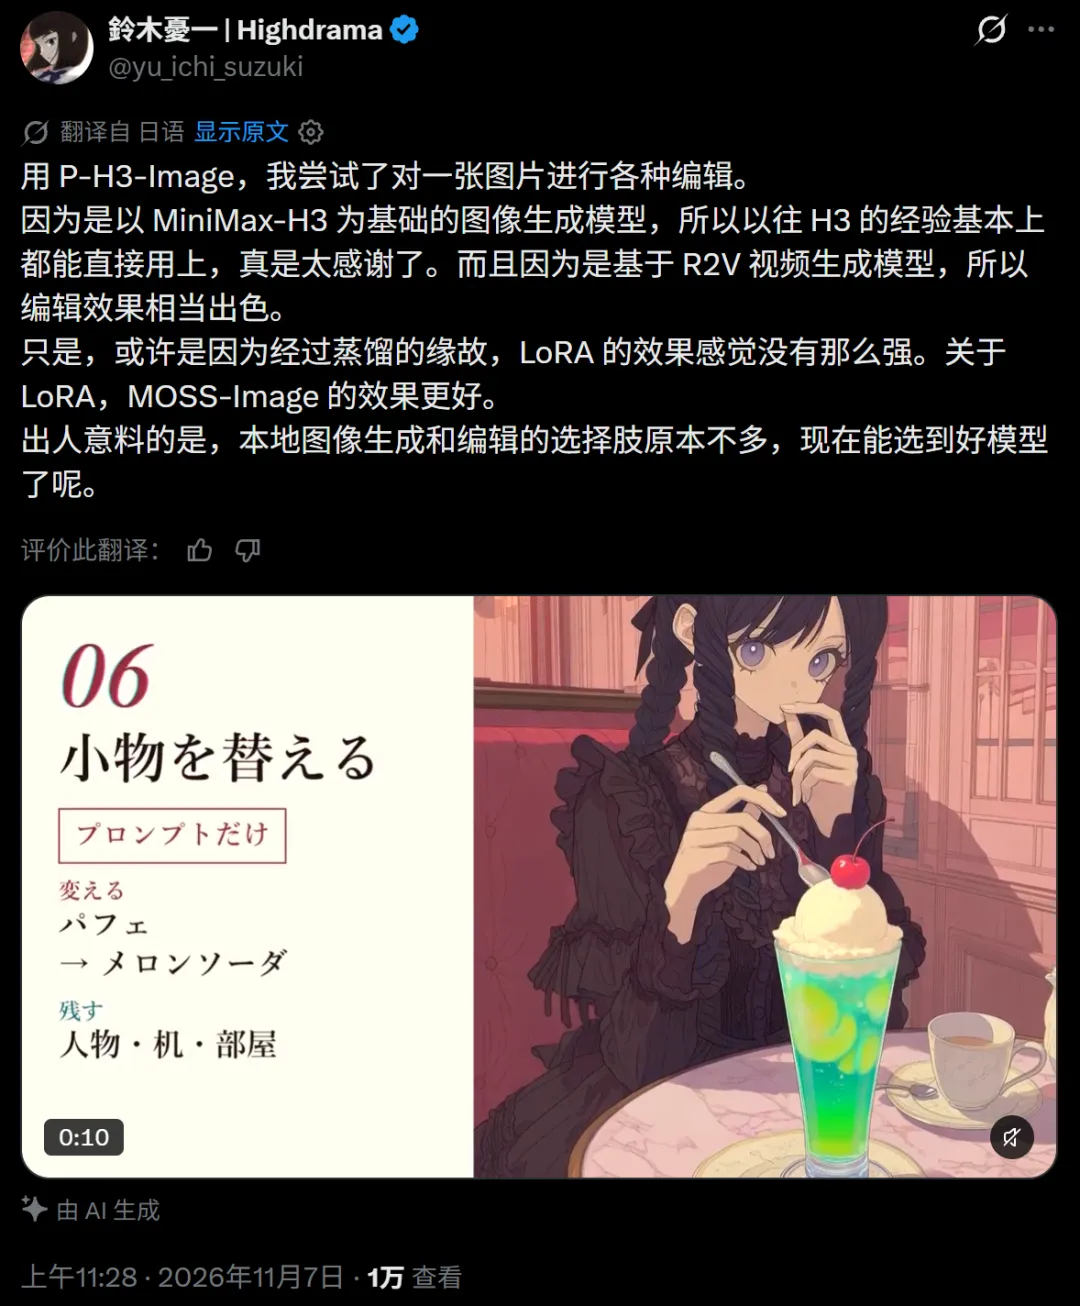
It is an open-source image generation model, and a startup company, Pruna, has also transformed the MiniMax-H3 into a high-performance image model that not only produces high image quality, but also low reasoning costs, and officially comes up with one.
Now that H3 Image is released, "the original version is here".
In fact, it is not uncommon to continue pre-training, tweaking or reinforcing on the basis of the weight of the MiniMax to introduce new models with improved capabilities. The day before the M3.1 Flash opened weight, American startups released a specially adapted model to help the M3.1 Flash produce text faster.
The derivatives around the MiniMax H3 are more active, with the Invidia team launching Sol-H3, optimizing the full logic link for video generation; Pika launching the Pika H3 Flex, reducing the number of generating steps, and improving image and creation controls. The MiniMax-H3-based model tree on the Hugging Face has captured about 220 derivative entries, with startups transforming the H3 into an independent image generation model, a video character replacement model, and even an interactive world model.
Domestically leading open source technology has become a priority choice for overseas teams.
The business model is also taking shape in this ecosystem. MiniMax is accepting consumption revenues through its free weight-taking ecosystems, using hosting APIs and subscription plans. The revenue thresholds in community licenses, hosting restrictions, will direct large-scale players to commercial licensing.
Looking back this week, the boundaries of the ability to generate image models have been redrawn for a few days, but what really determines the long-term format may not be the highs and lows of the runway, and open-source ecology is defining the breadth of the distribution of capabilities. When 4K production, dozens of reference charts, these front-end capabilities become available to humans, the core of the competition has become "who's ecology is better".
The next AI breakthrough may have been in the hands of a developer who downloaded H3 Image.