Jay from the Monastery of Panfi
QbitAI is public.
It's bad, it really makes the MiniMax a multi-modal game.
Following the widespread acclaim of the open-source video flagship H3, the latest image model emerged.H3-Image, once again sweeping the web。
The heat is the "CAD demolition", drop a reference map and H3-Image can open the box directly to your small office.
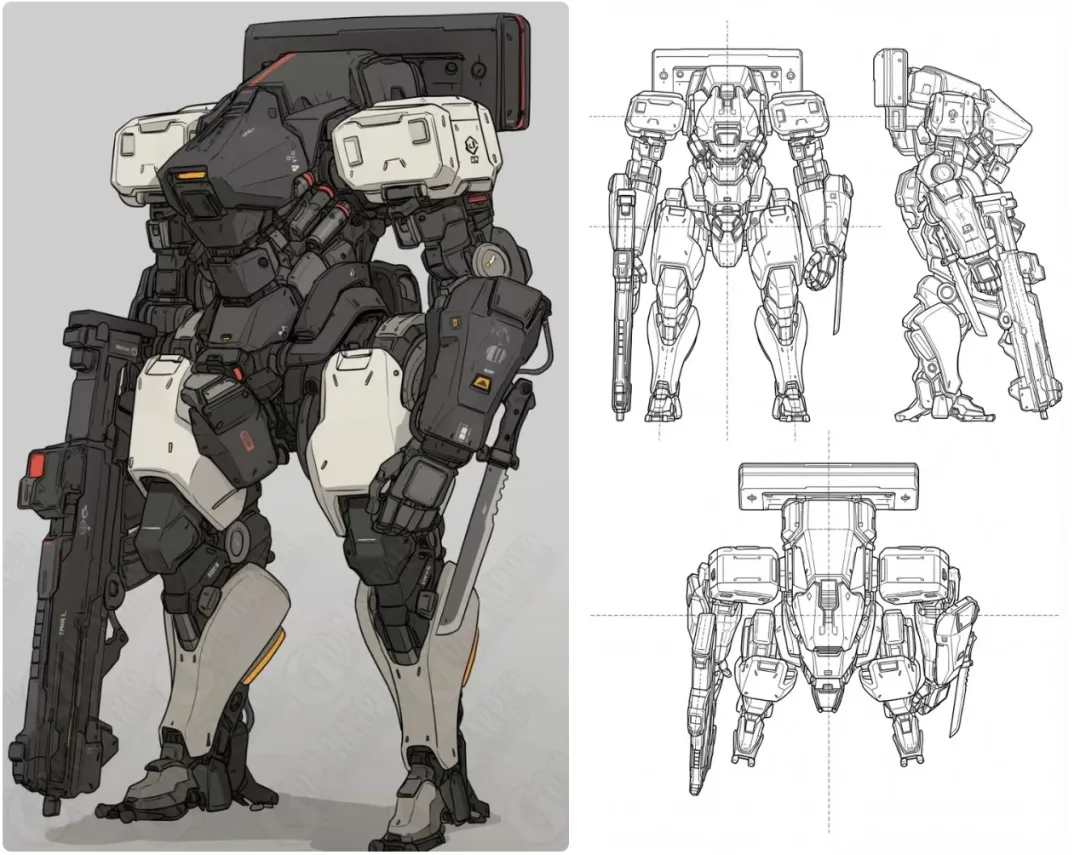
I'll give it to you.U-tree machine dogIt's CAD.
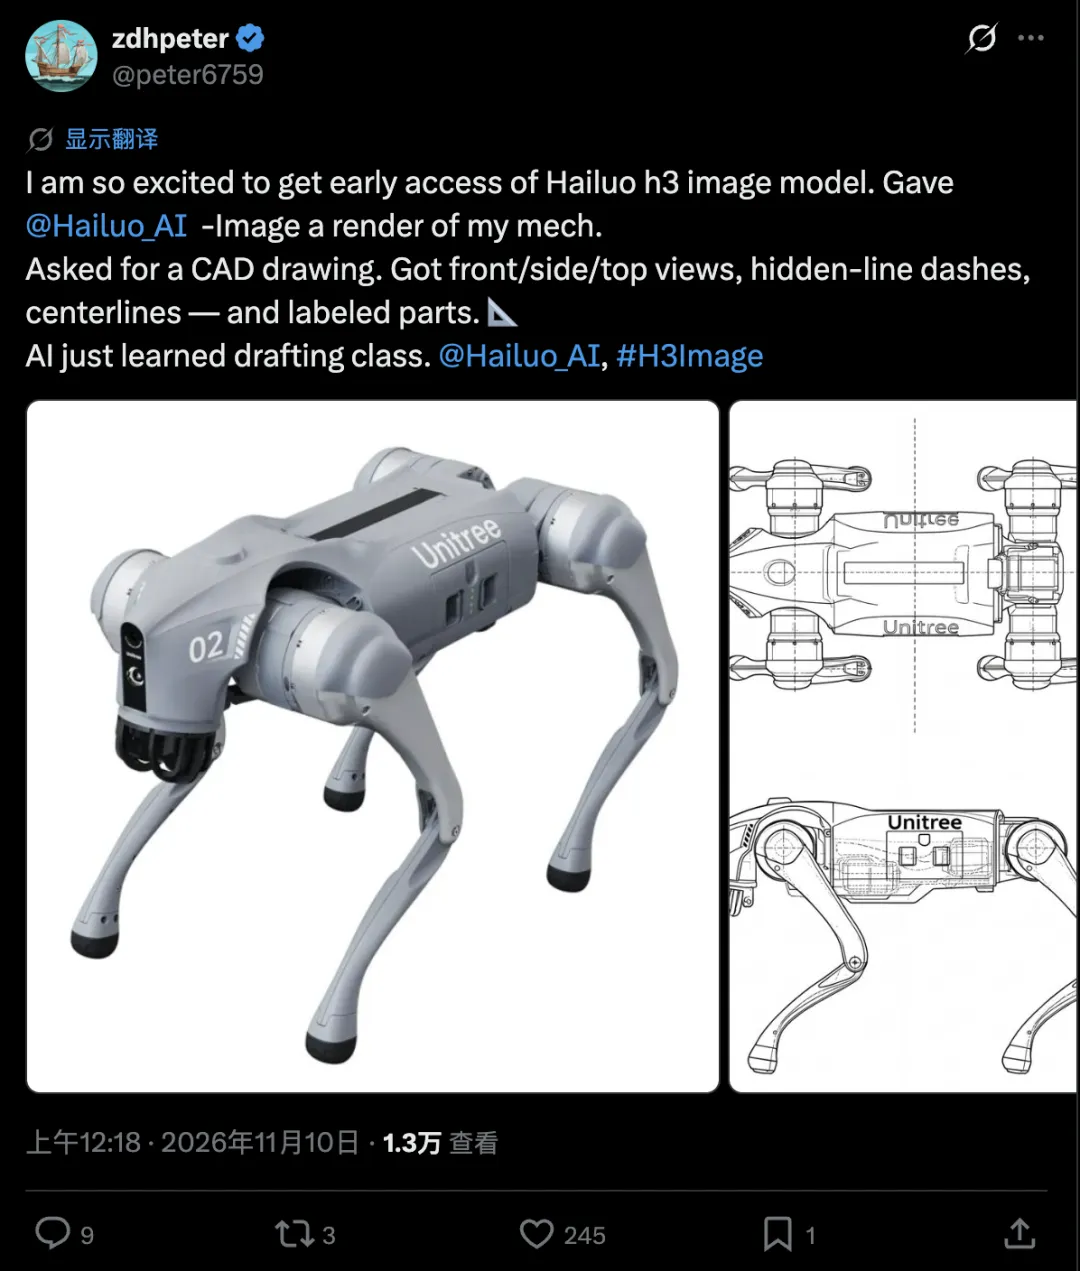
In short, everything can be dismantled, and you can make the parts fit.
I also checked it myself, and don't tell me, there's something...
In addition, overseas netizens have estimated that other types of complex bio-graphic tasks can also be handled, such as crawling.Games。
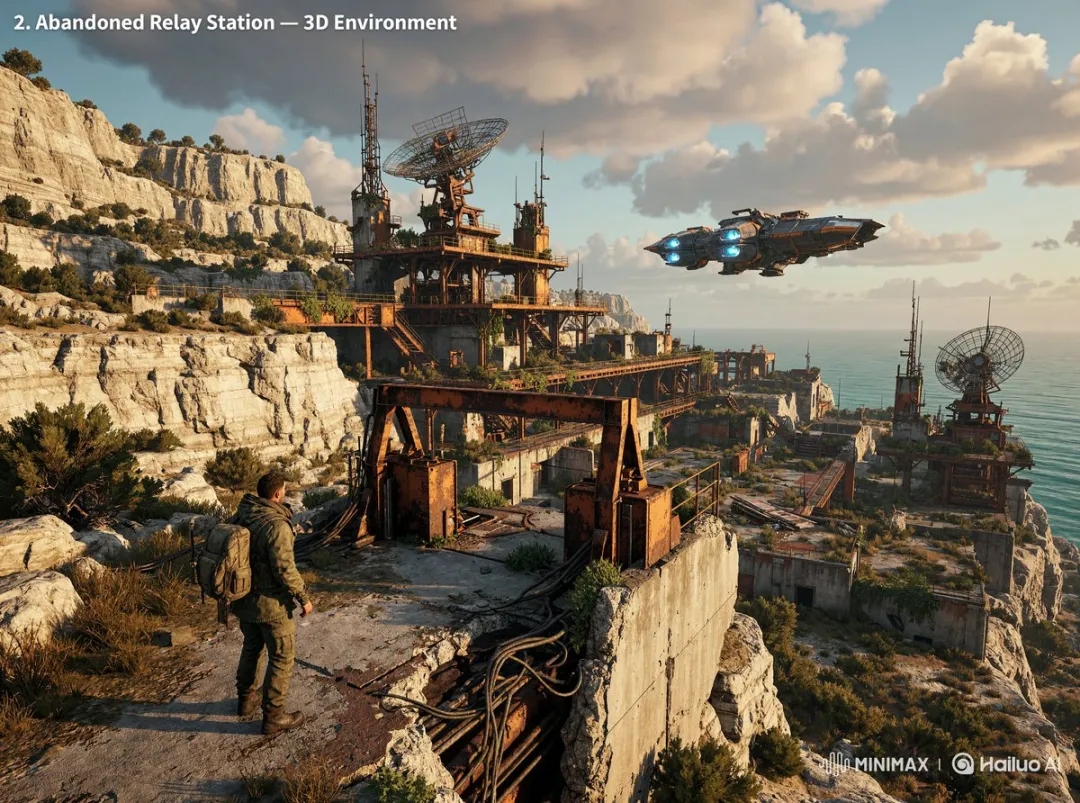
This is not what you said, I thought it was GPT programming.
It would have been easier if it was just a simple asset for e-commerce.
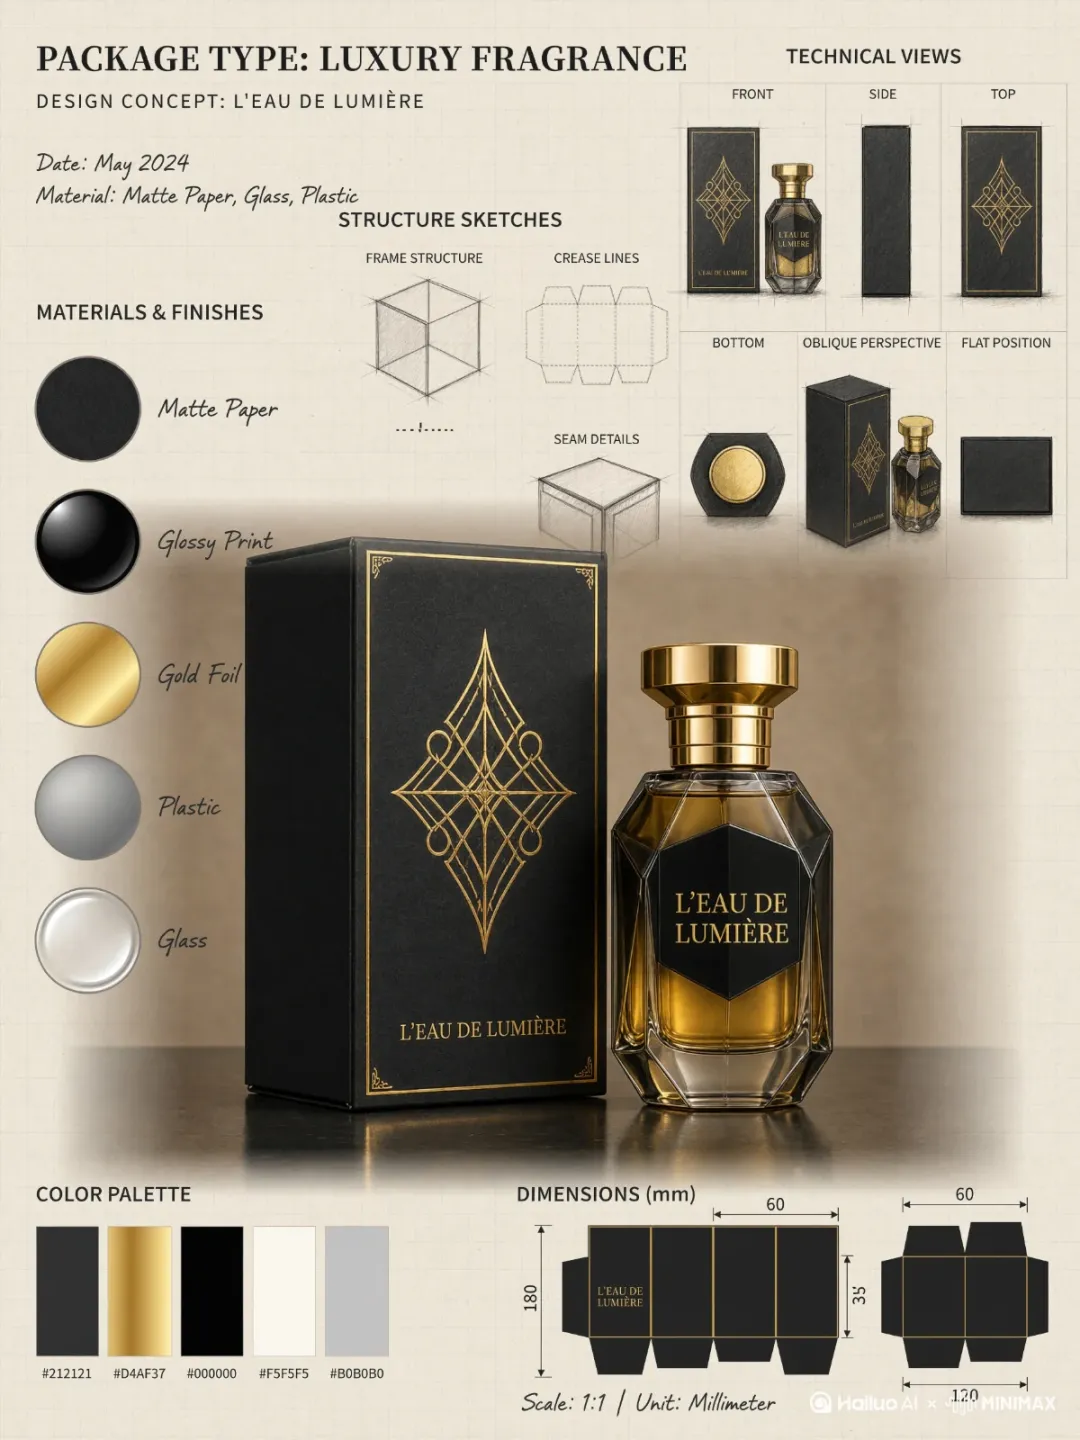
But what I didn't think was that this guy was a literary jumper.
There is also something about the aesthetics of H3-Image, given the assurance of IQ.
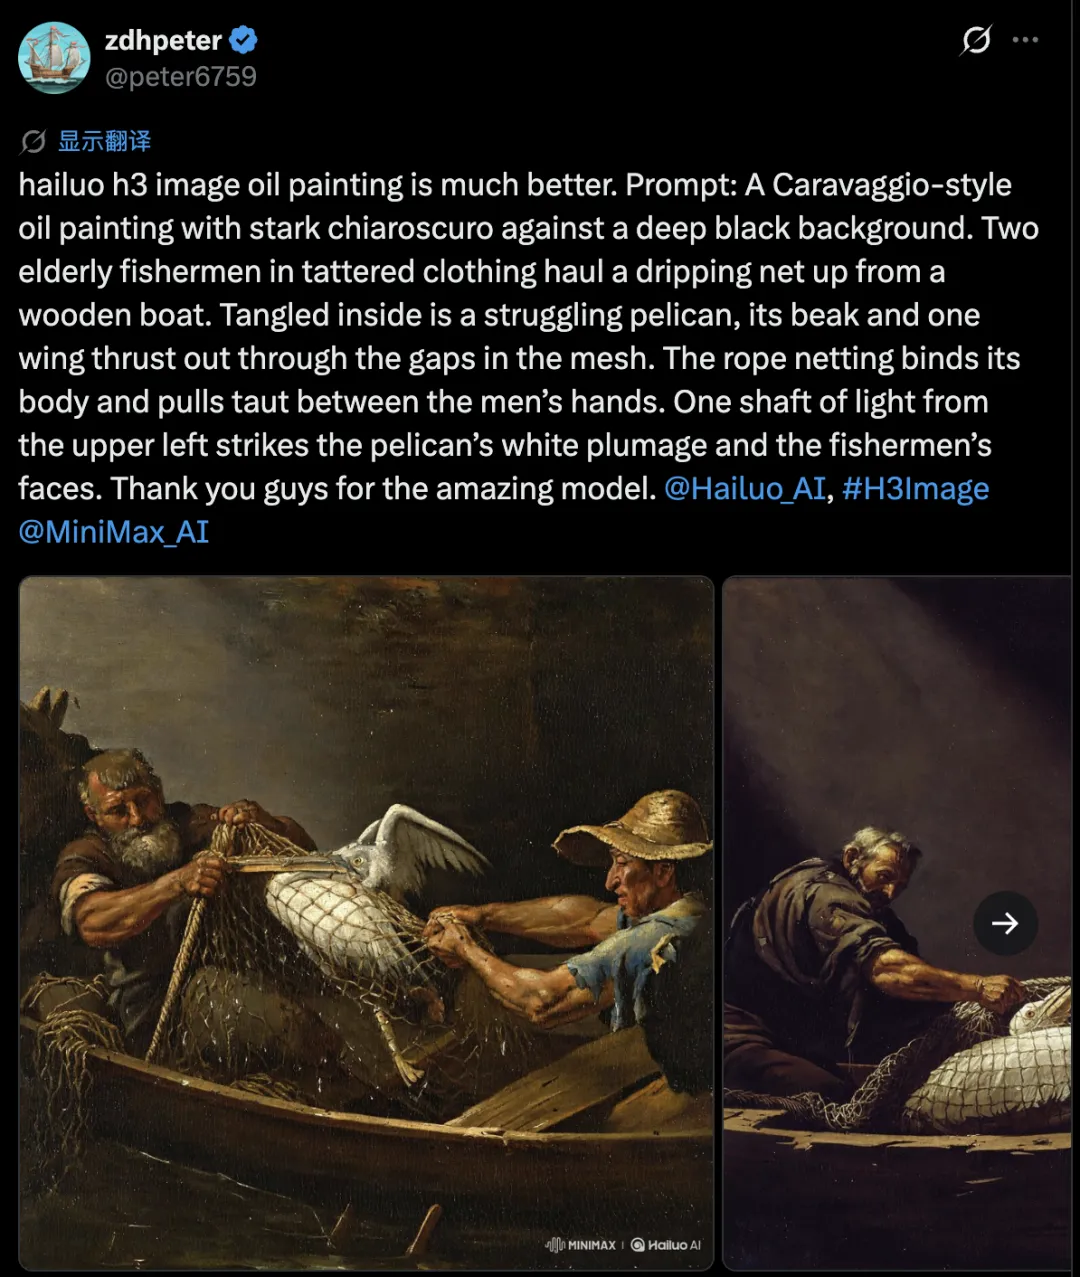
That's right, there's something else.
This is a model that generates images of this quality.Are you saying it's open source?
That's what it's all about.
I declare that MiniMax is the "Goddess of the Multimodal Realm", Bushi.
Say goodbye to plastic "American business".
In the past, when we talked about AI images, the first reaction in the brain was: the face is full of oil, the skin is as smooth as the eggs, the eyes are stagnant, the hypocrisy is intense.
It's a bit of an "AI" smell.
GPT Image 2 has made great strides in this regard, but after a lot of use, the effects of the Valley of Horror are still coming to mind.
This time around, H3-Image, I feel, should be a fundamental solution to this problem.
I was born a fool, not a brother, who can see that this is an AI?
Most importantly, the faces, the holes, the sparrows.Even the hair.I drew it for you.
In addition, the details, like the water and dust on the mirror, and the flashes of light that form on the mirror, are treated very oddly, just like the first page of a small book.
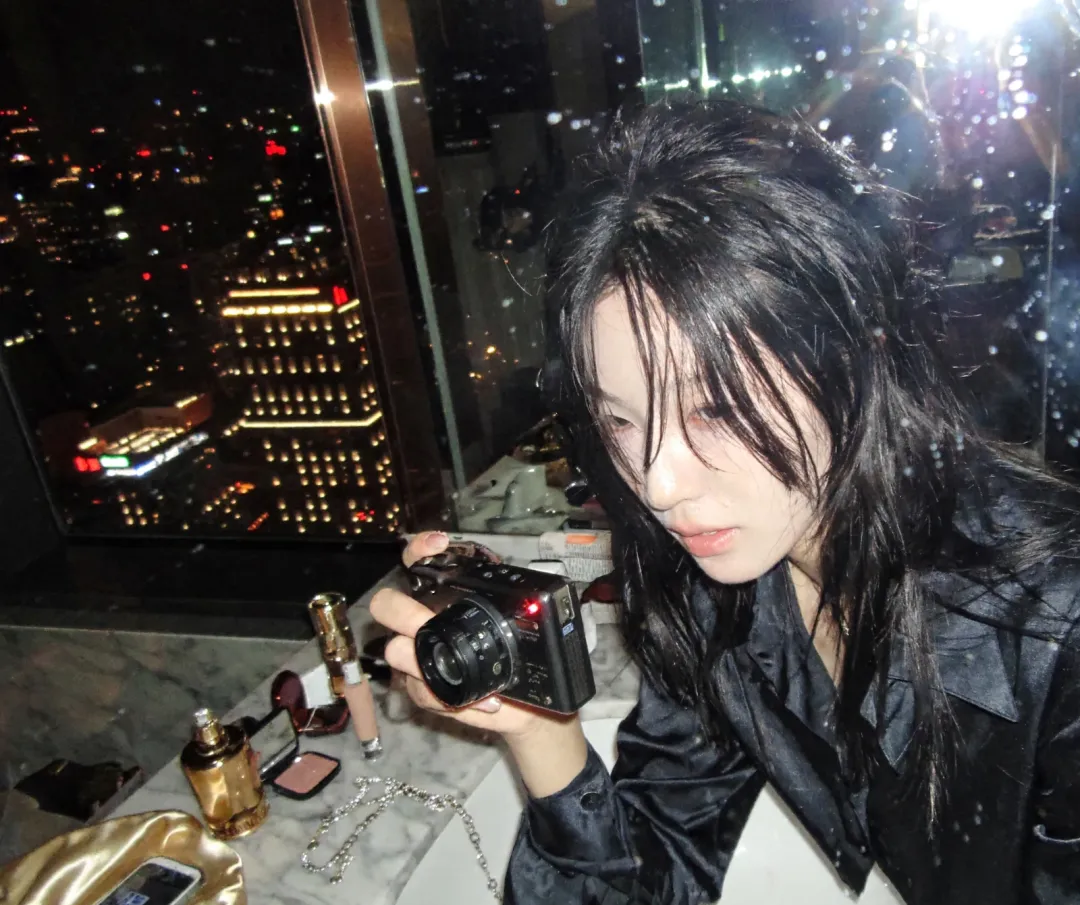
Even if you can see a lot of facial details from a glance point of view, you can see a lot of facial details, like the one below.The table is ins photosThe covers of fashion magazines, the look in the eyes of the characters, and the delicate muscular pull on their faces are all very much in line with the social logic of reality.
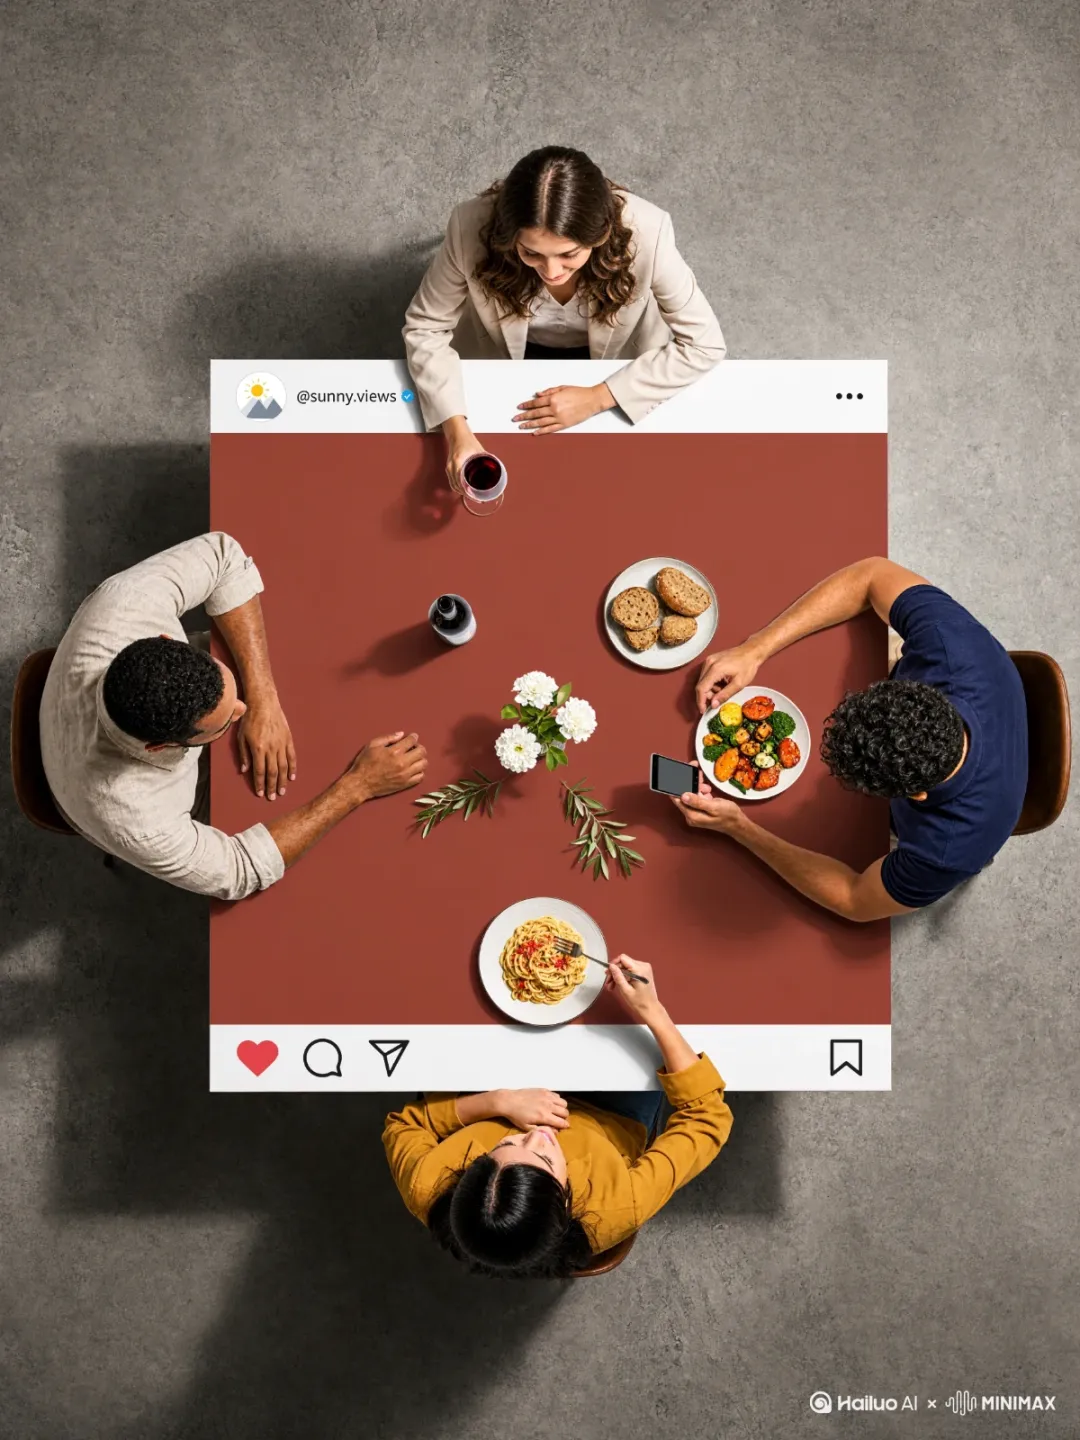
It's also one of the biggest feelings I've ever had when I tested H3-Image, and many of the tips I've given to old models give H3-Image a whole new interpretation.
In fact, the world is rich in knowledge.
As for what is outside the face of man, it is even more so with his hands that he touches his thumb.
For example, the city's landmark in Rio de Janeiro was made into a traveling handkerchief in the style of a cubic-paper sculpture.
Microscopic landscapes, shadow thickness, hmm, always feel like a part of it.Fable 5The smell of propaganda.
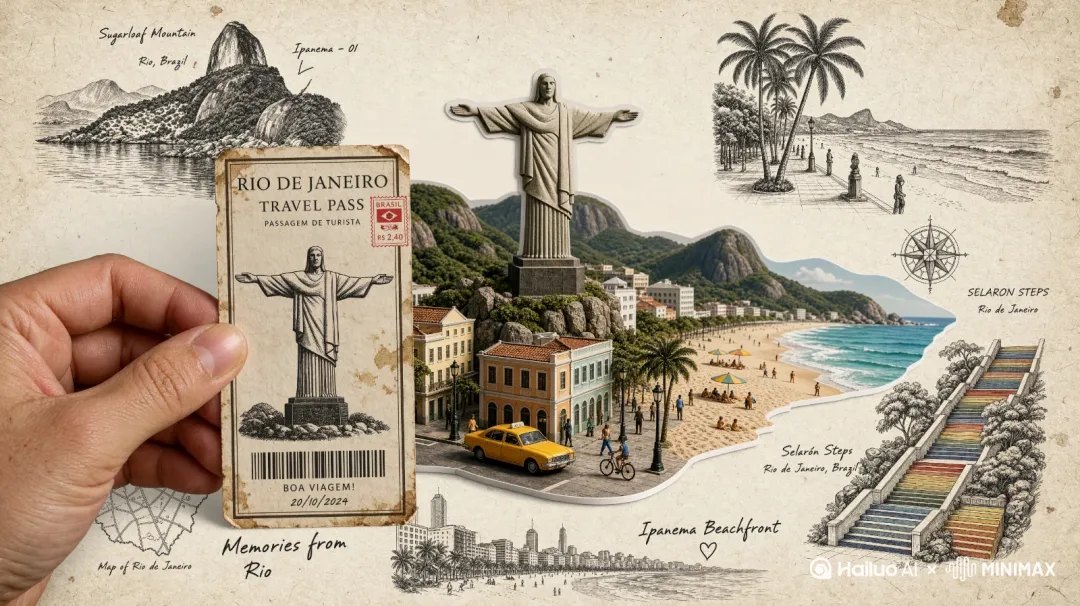
And indeed, a small foot was exposed.
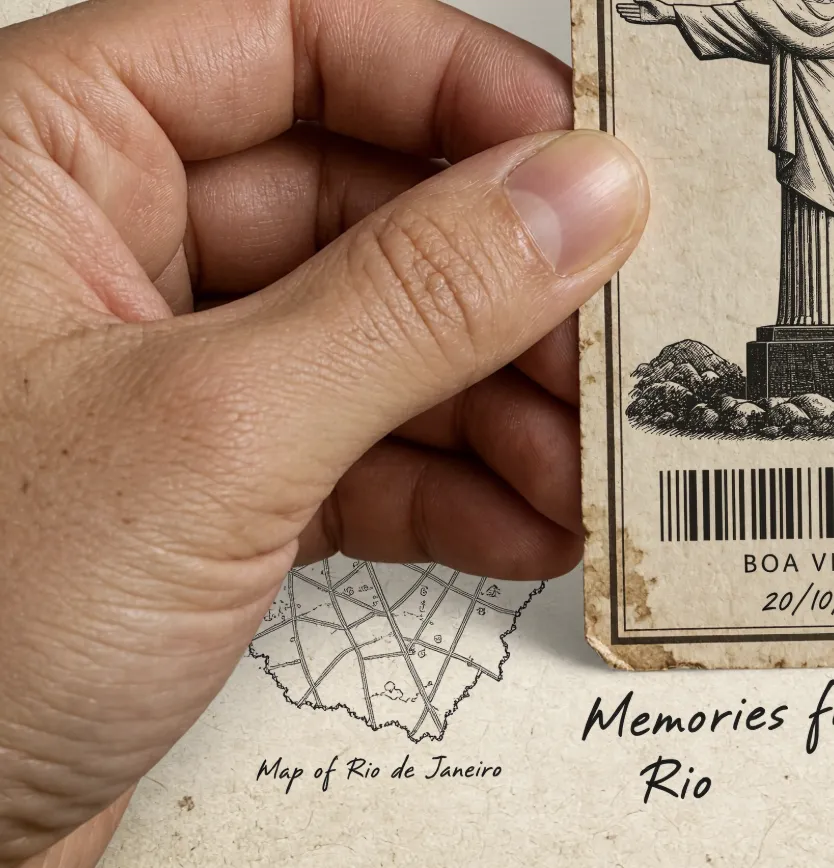
You look at the bottom left corner, and you see no,It added a few stitches near the thumb joint!
The exaggerated appearance of the skin on the fingers, the texture of the joints, and even the natural gloss and texture of the fingernail edges of the fingers are completely restored.
It's funny.
I think that the reason why H3-Image has so little taste in AI is probably due in large part to this.It's an intentional "hump".。
Any human subjective creation is bound to be full of randomness, excessive pursuit of the perfect opposite, and not in line with the human brain's habit of receiving information.
But that doesn't stop me from getting a little pissed off.
I have always been adamant that aesthetics are not something that machines can learn.
Now, it seems that as long as we can understand the tricks, many of the qualities that humans pride themselves on, may not really be so mysterious...
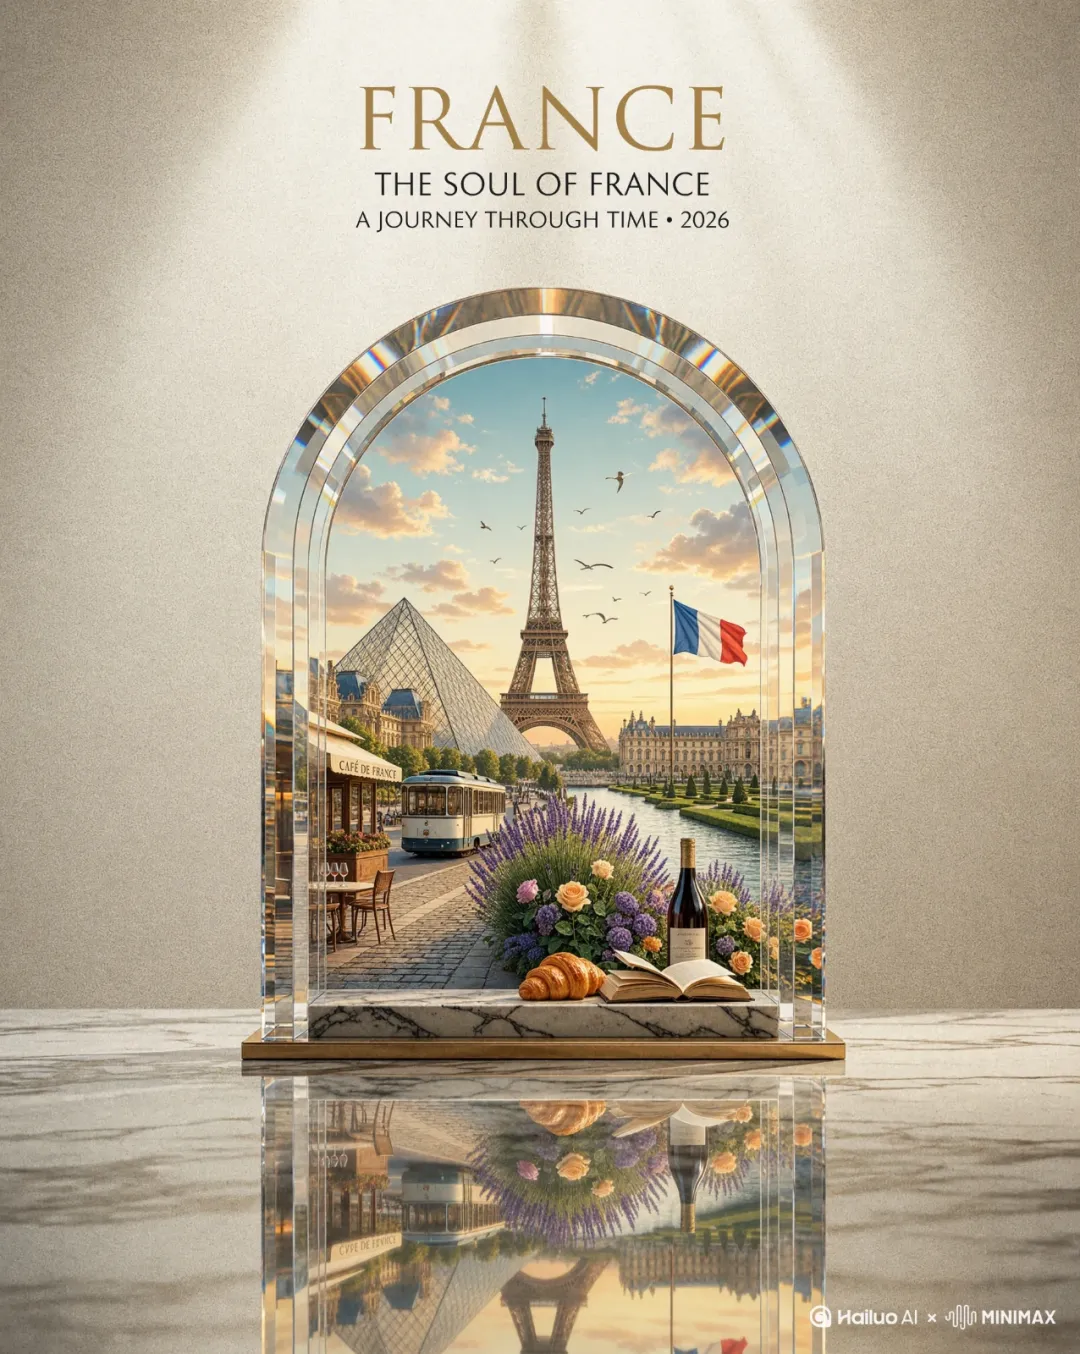
I'll show you the demo again, and I've got H3-Image.French Tourist Posters。
I'm not ashamed to say that the artist's talent is completely out of the way.
Oh, my God.
SOTA-level intelligence
It's not like I'm going to be able to do things that I can understand myself.
In terms of multi-modal models, I've always had two judgments: Aesthetics and Intelligence.
It's just that the American business is what we're talking about, and it's more of a conversation about subjective feelings.
But the IQ can speak for itself.
H3-Image, for example, has a very special ability to understand the world.
You can generate it.CAD drawings。
Yes, it's the look and feel of a product that you give it, and it automatically triggers the performance standard.
It's a good point of view, a side view, an overview.
My family, I'm so soft.
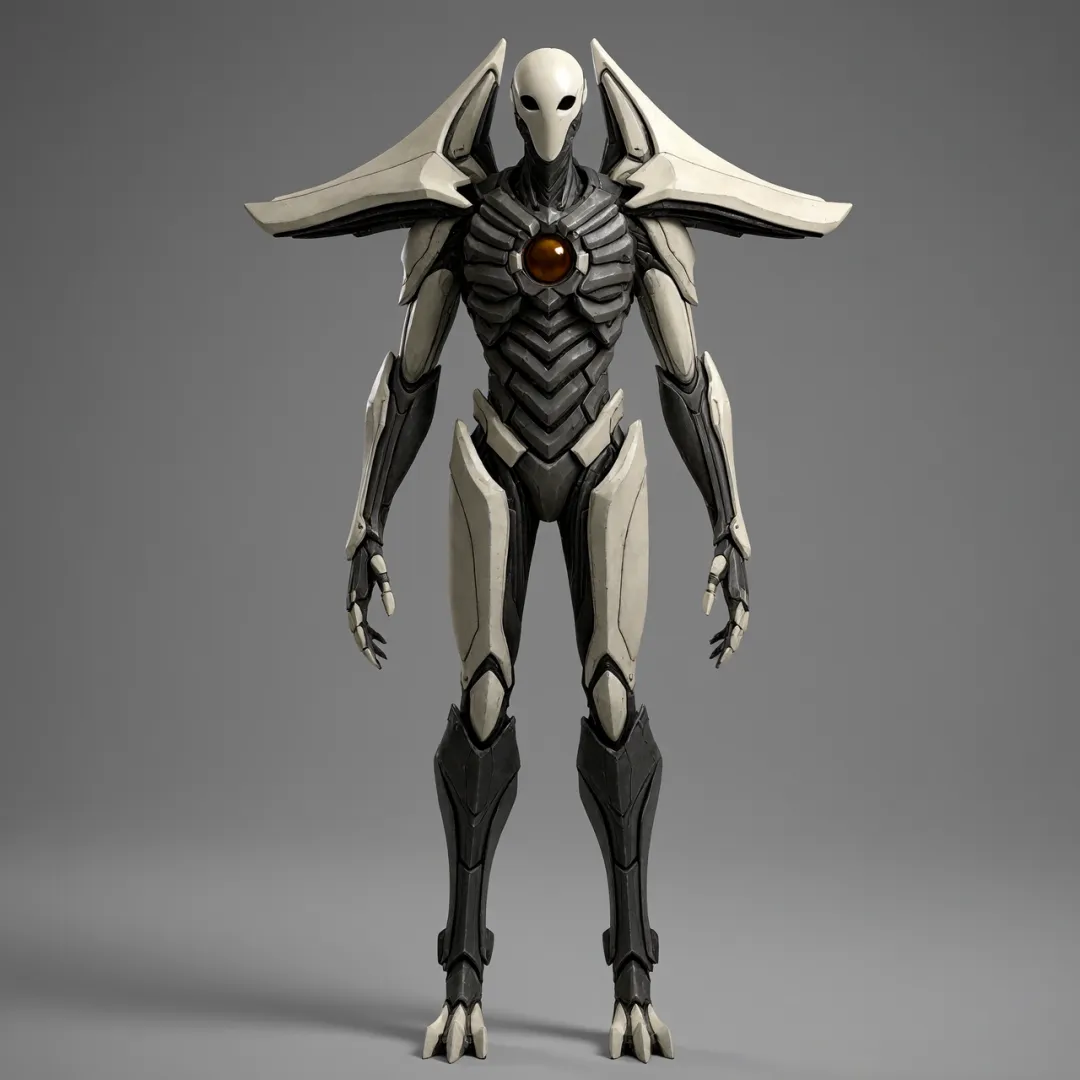
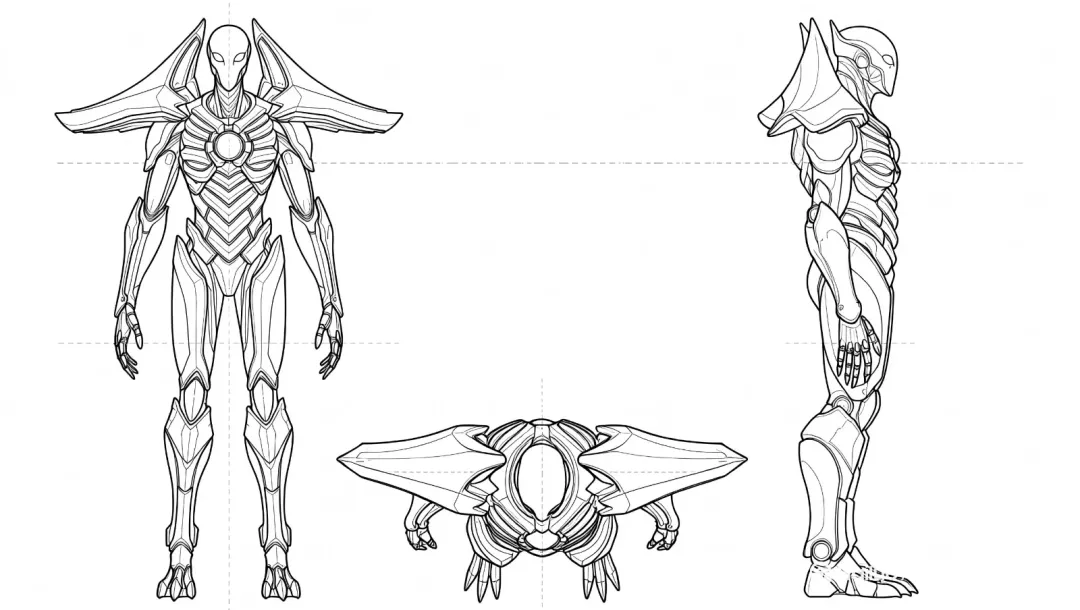
It's not over yet.
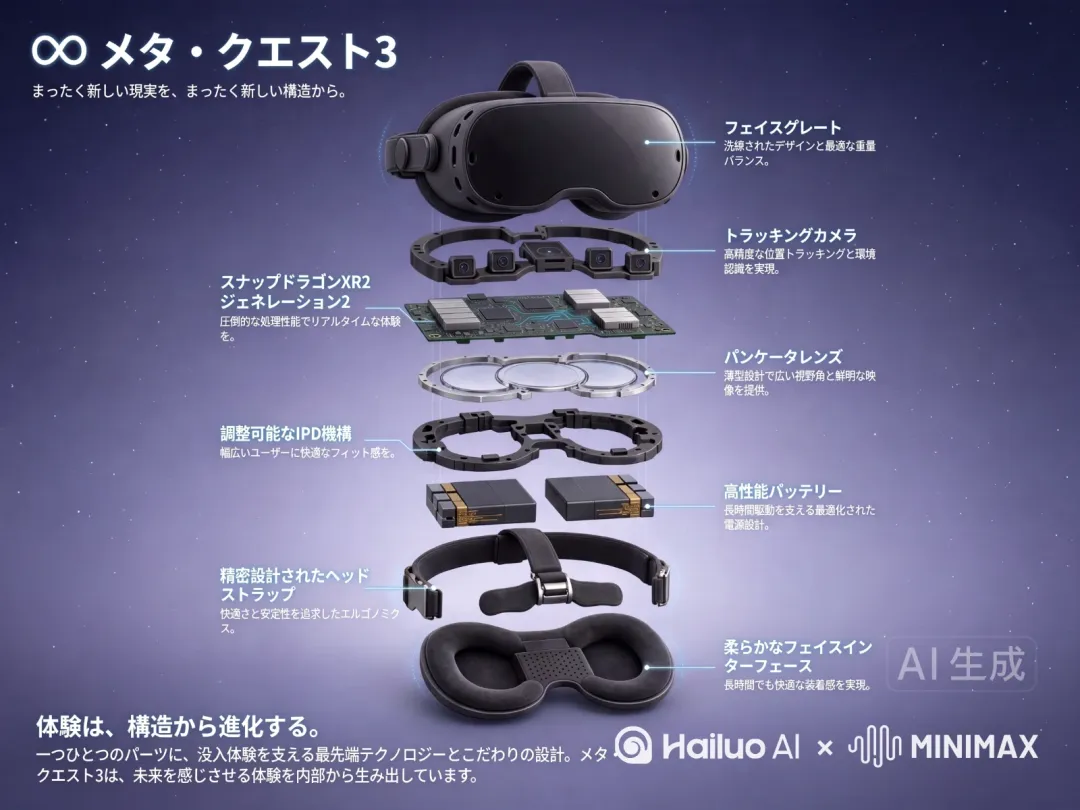
In addition to CAD, you can also make this model explode.
Let H3-Image draw an explosion diagram of mechanical dismantling, which can accurately follow the mechanical assembly logic, and explode the parts in layers that give you a clear indication that even the component leads you to the label.
There is no doubt that this requires a deep understanding of three-dimensional geometry and spatial relationships.
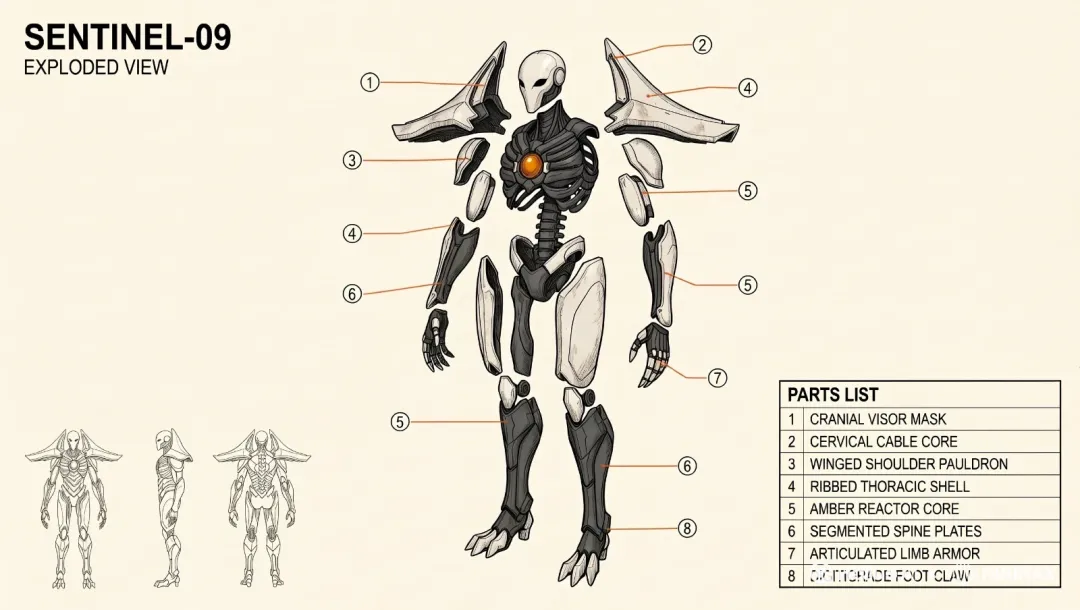
Of course, the ability to follow instructions is also very important for images that have obvious functional properties of this kind.It's not that difficult to paint.This is mainly due to the ability to test model planning and reasoning.
If you don't, you don't understand what a bunch of user hints are saying.
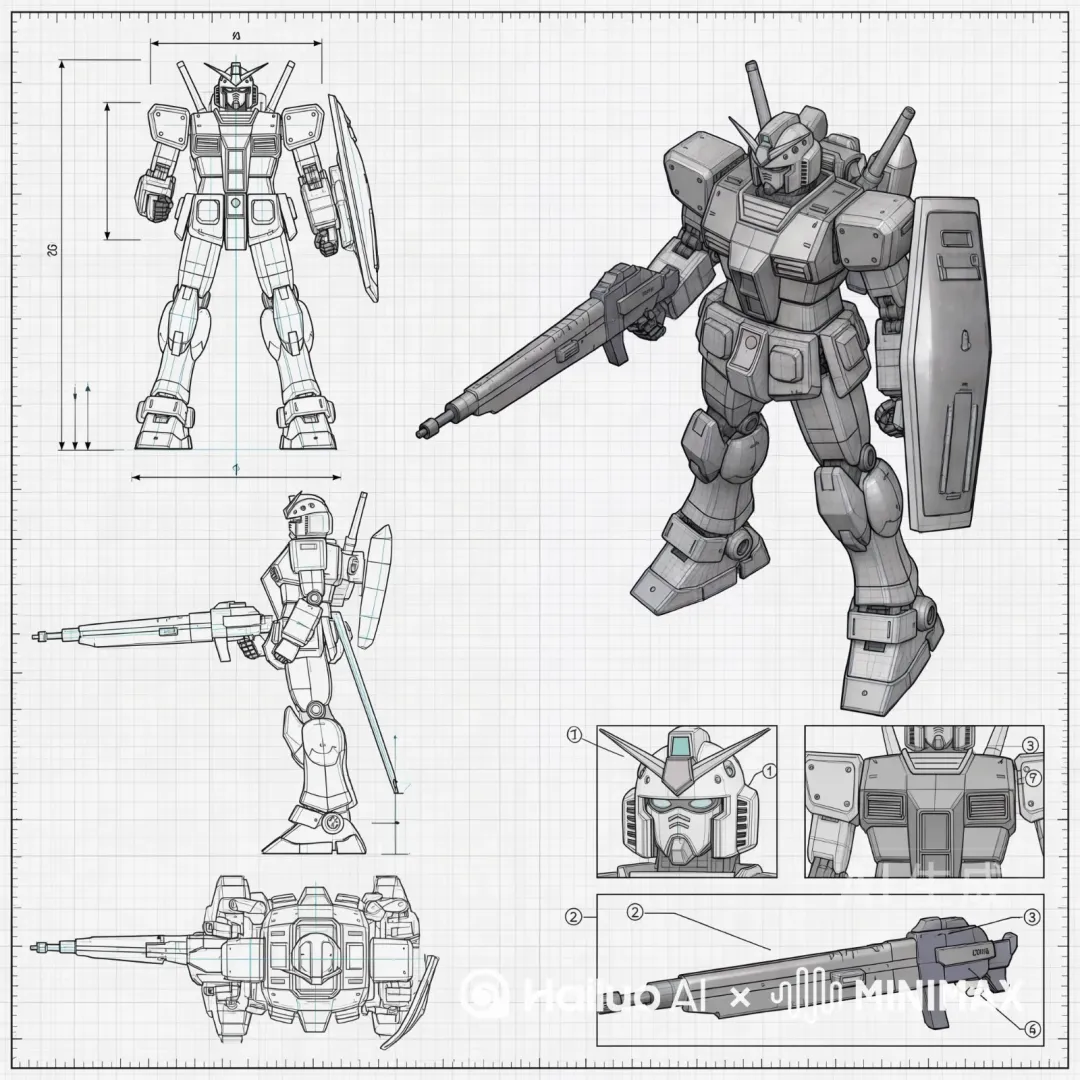
Of course, if you want to play a serious productivity scenario, the standards must be very high, and the commercial use must be accurate.
In addition to the understanding of space, this dimension is also very important.
So I did something like this again.
I'm going to make one.High end exams。
It takes more than ten seconds to generate.
Limit symbols, complex punctuation... this high-density academic arrangement, and none of the characters are decoded.
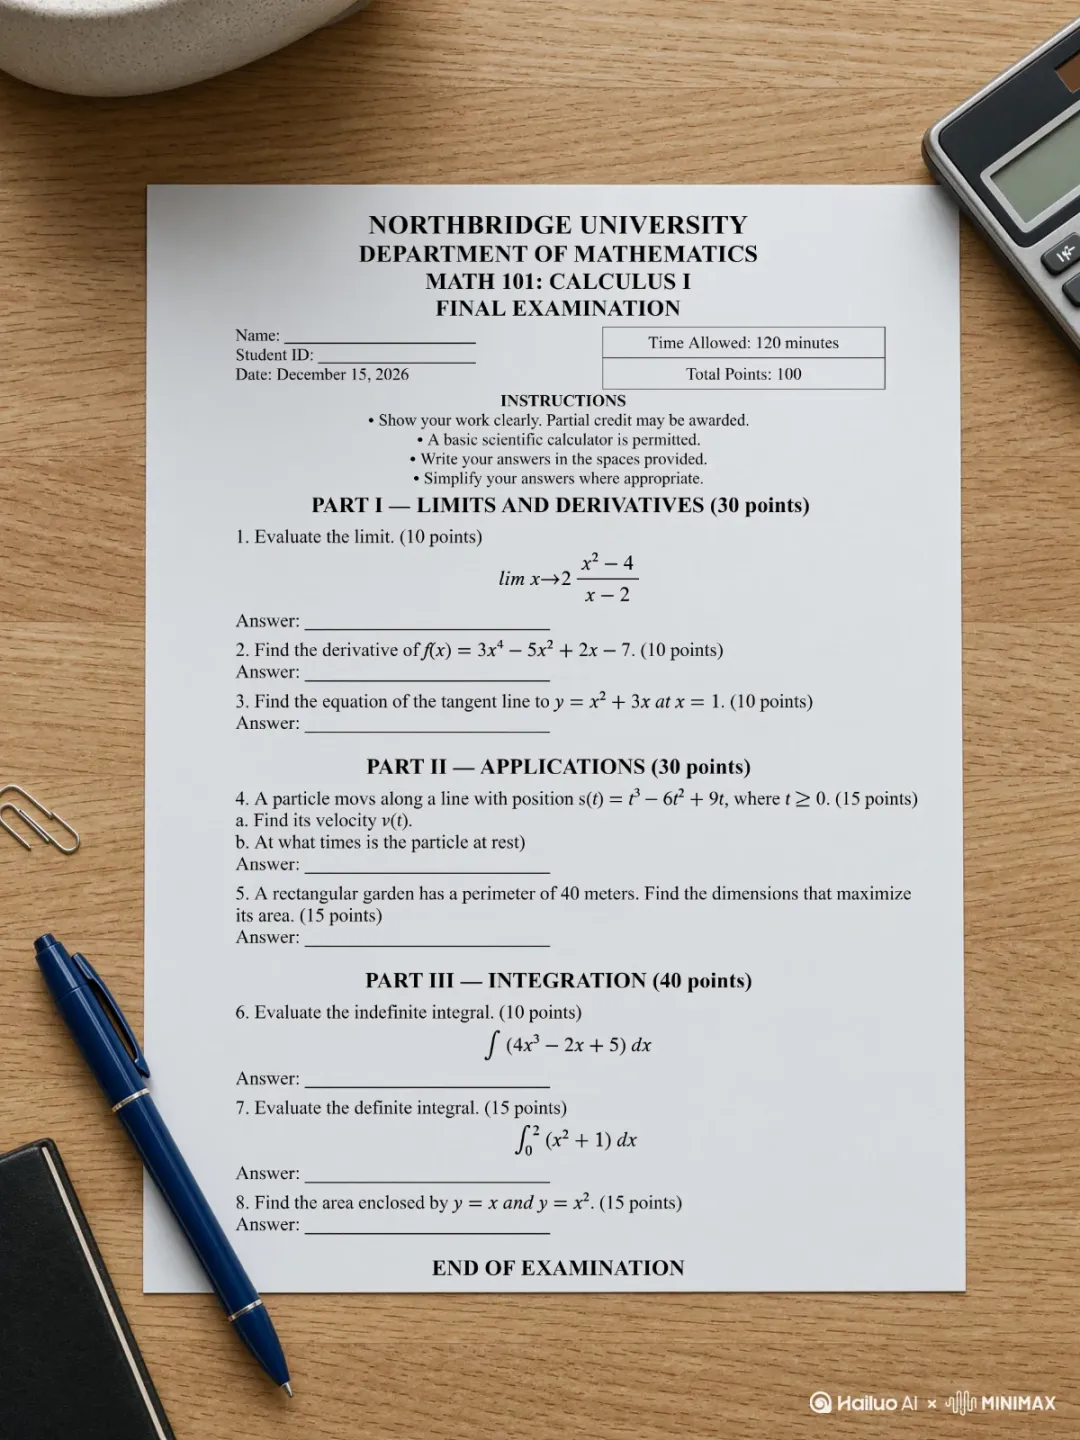
I thought it would be too simple, so I came up with a genius tip:
It's time to finish this exam.
When I opened it, it was like I saw a chair explode.
Why is it that the level of calculus of an image generating model is stronger than me?
With the huge amount of knowledge available in the industry, I probably looked around and found that the answer was right, and there were steps to solve the problem!
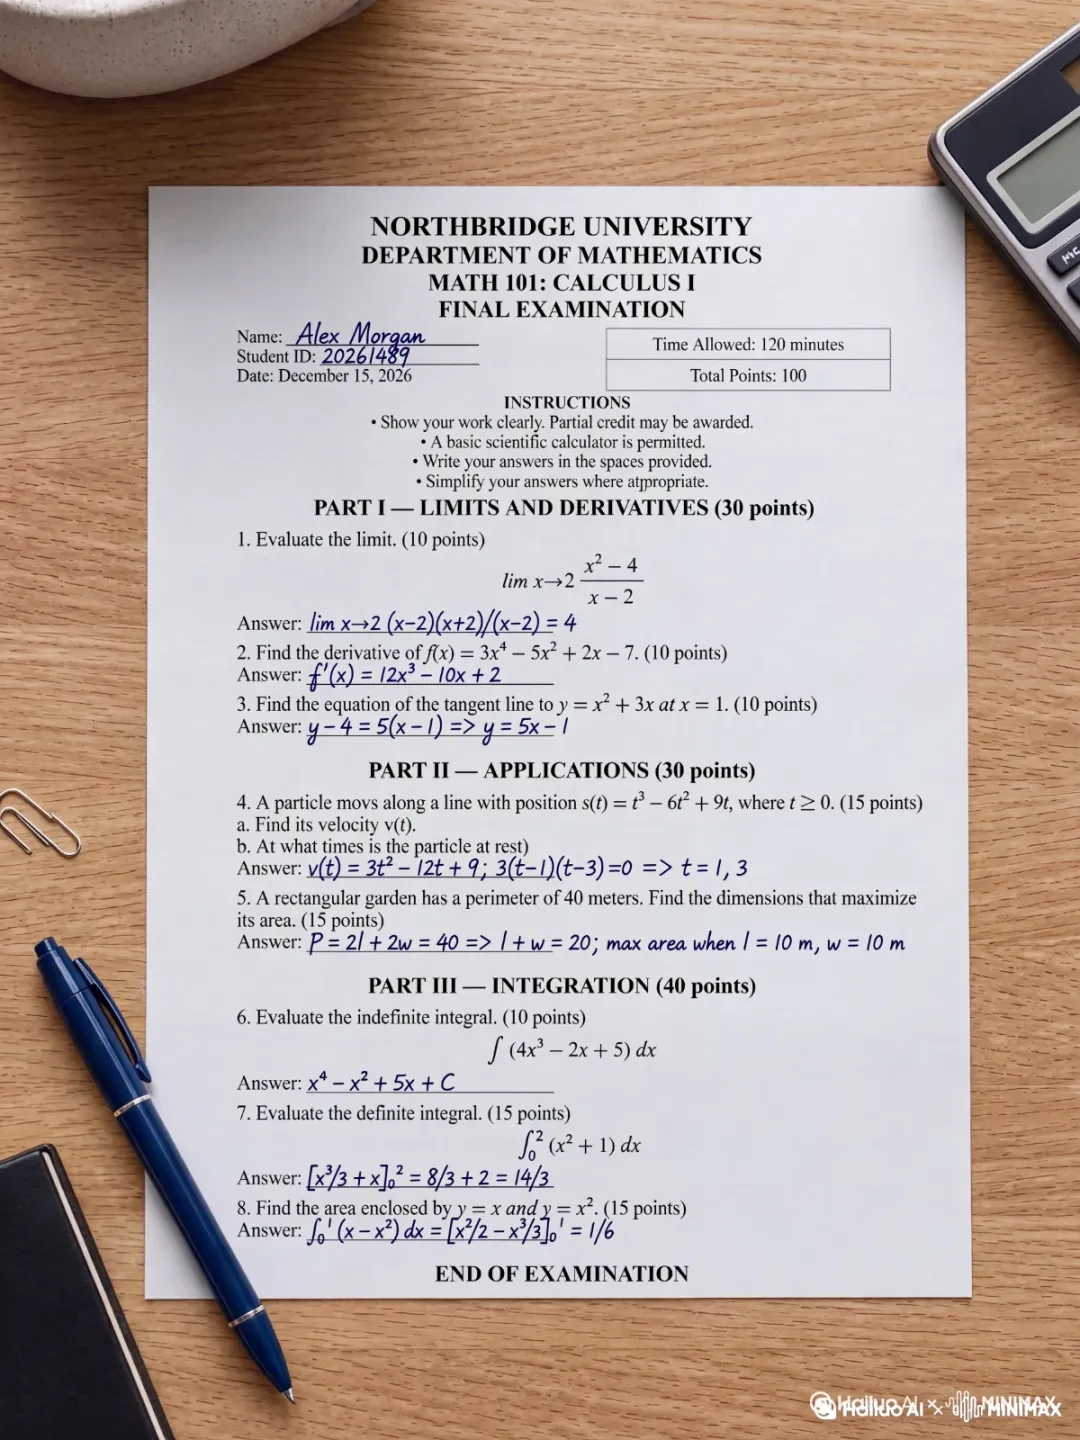
For a while, I was silent.
Of course, the old line,Asset generation cannot be diminished。
Now isn't popular coding eating everything, Astra downsizing 3D, Opus 5.5 downsizing video?
But I've always felt that there's a lot of propaganda that can't be done with eight bars of text, so why should I use a text model?
The only thing that can be said is that there are more resources in the field of pure text, and the development is relatively fast.
Based on the principle of primacy, I still believe that the path of the vertical model, in different areas, the ceiling will be higher and the cost more realistic.
And this vertical model, like H3-Image, is a natural selection, and it's perfectly consistent, and it's perfectly suited to Harness.Let the Agent directly call the tool.。
This is a trend that has recently begun to emerge, and it is not necessarily a single model that reduces everything.
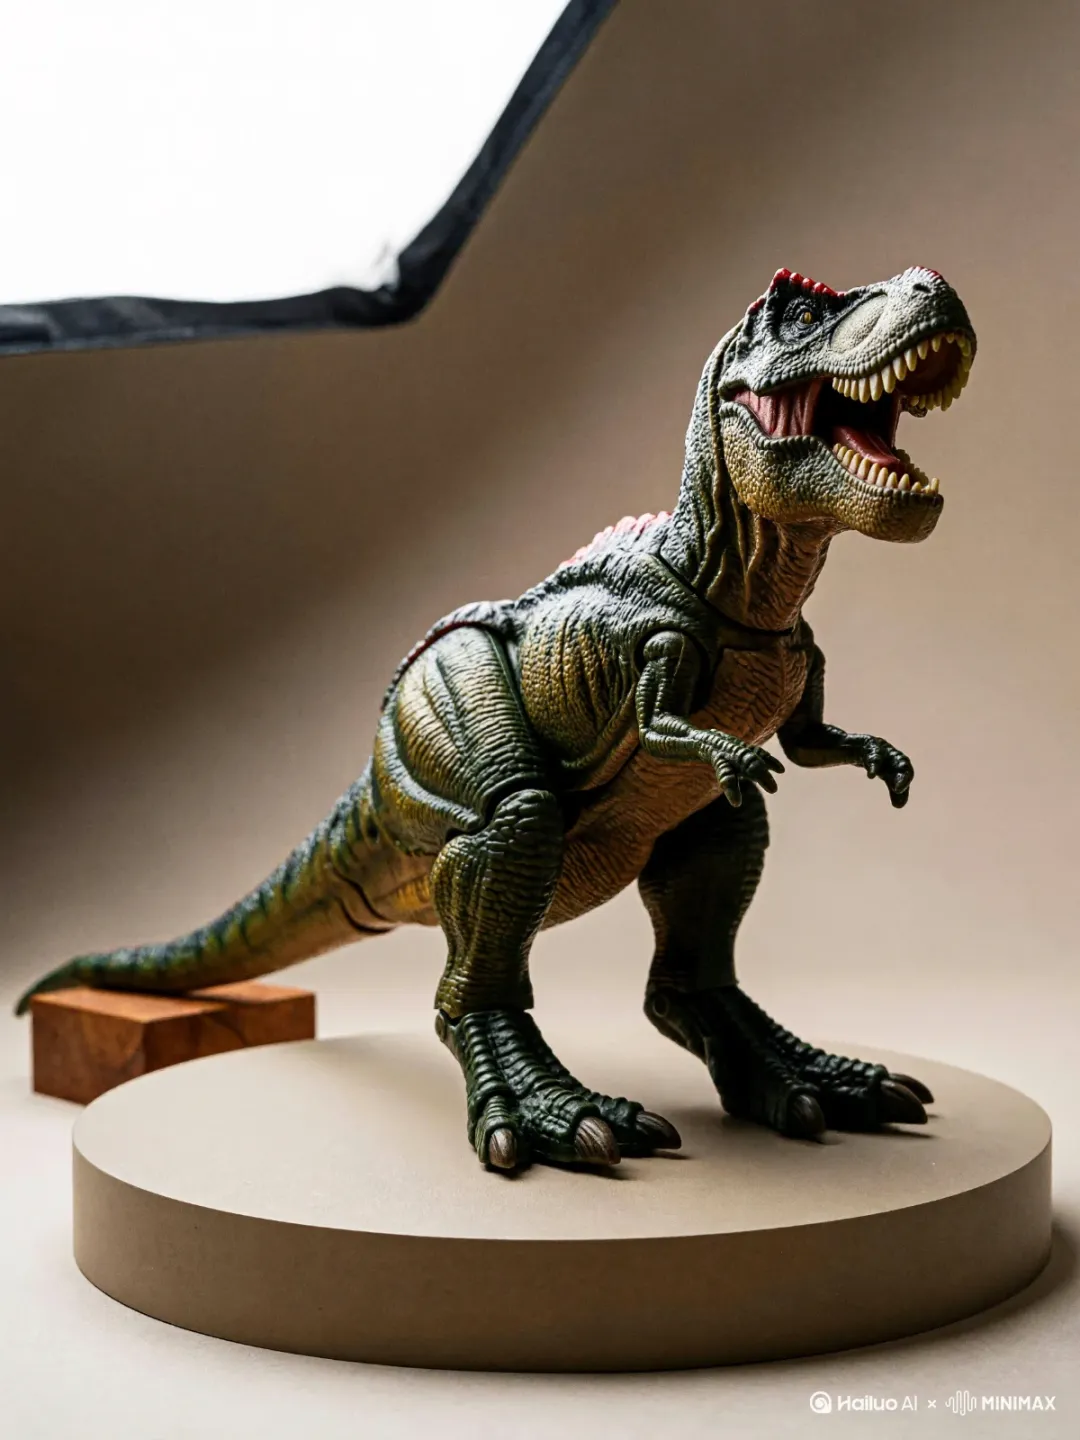
If only the assets were generated to be displayed, such as the dinosaur toy below, the vertical image model would be significantly more optimized, without the need for Computer Use half a day.
After all, basic physical knowledge of image models, photosynthesis, and geometry is no longer a problem.
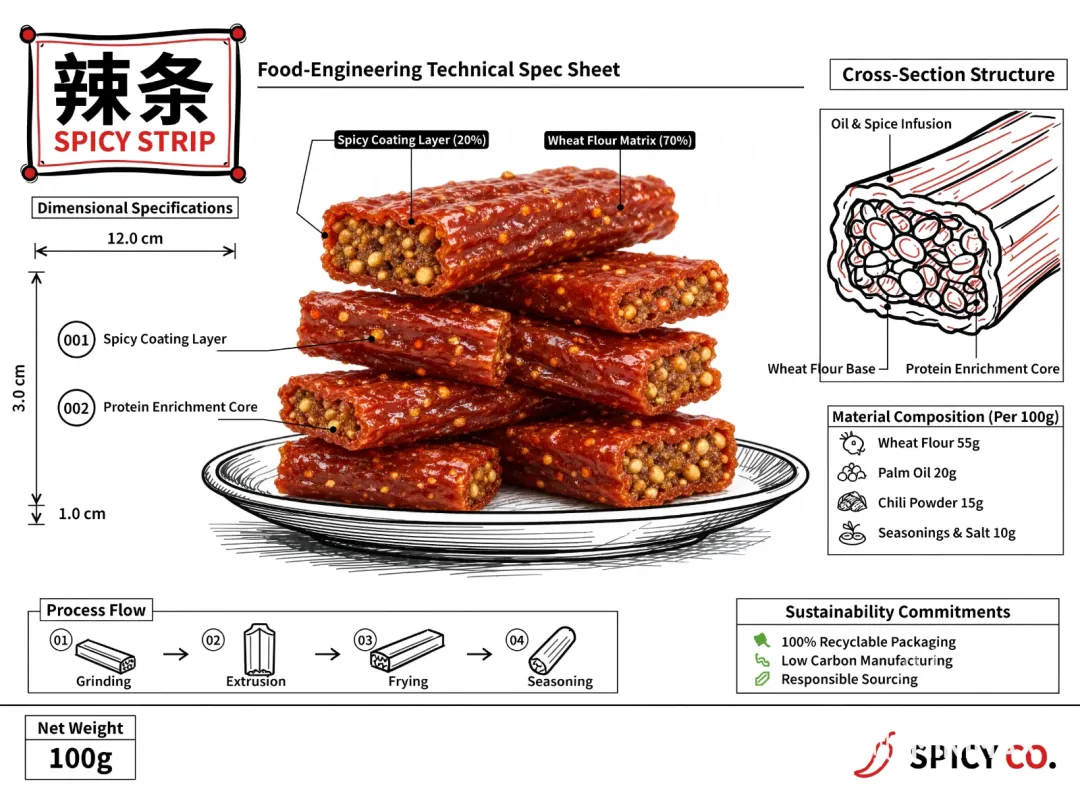
It's not a problem with snacks, and look at how I did.China's Depression to the World。
Even 3D video games can be generated, but the sky's the limit.
A long-text tactical instruction on what to do with a cover, fire suppression, side-wings, can instantly create a 3D battle scene with a real depth of field and a reasonable shadowing relationship.
It follows strictly game terminology and can be used almost directly in conceptual design.
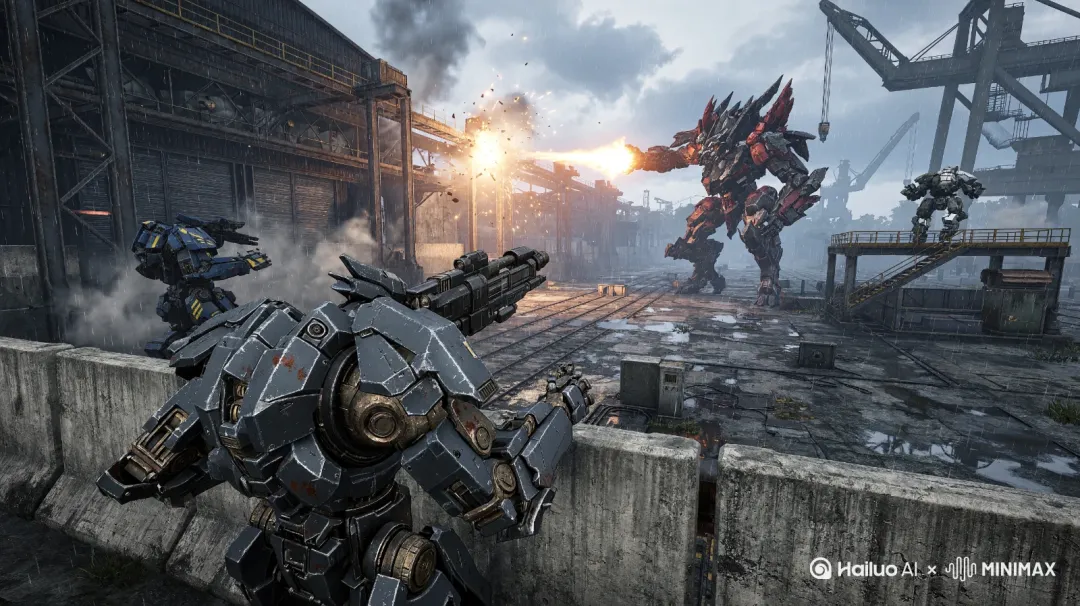
This is my Astra Ultra.It's all about seeing a demo and generating a few pictures.
(bushi)
Multimodal "God of the Source"
Basically, in addition to this, as a flagship image model, H3-Image also offers some small benefits.
And most importantly, H3-Image does it directly with the resolution.16MPIt's actually 4096 x 4096 pixels, or 4K.
Looking at my family, I finally gave Nano Banana half a day to optimize after I hadn't finished using GPT.
And 4K is so fast, it's so big, I can feel it on the web.10 to 20 seconds.。
However, who wouldn't want to wait for GPT to grind the potatoes, when Amelia comes and eats a snake?
It's too far away.
In addition to these, H3 has a relatively special array of parameters.
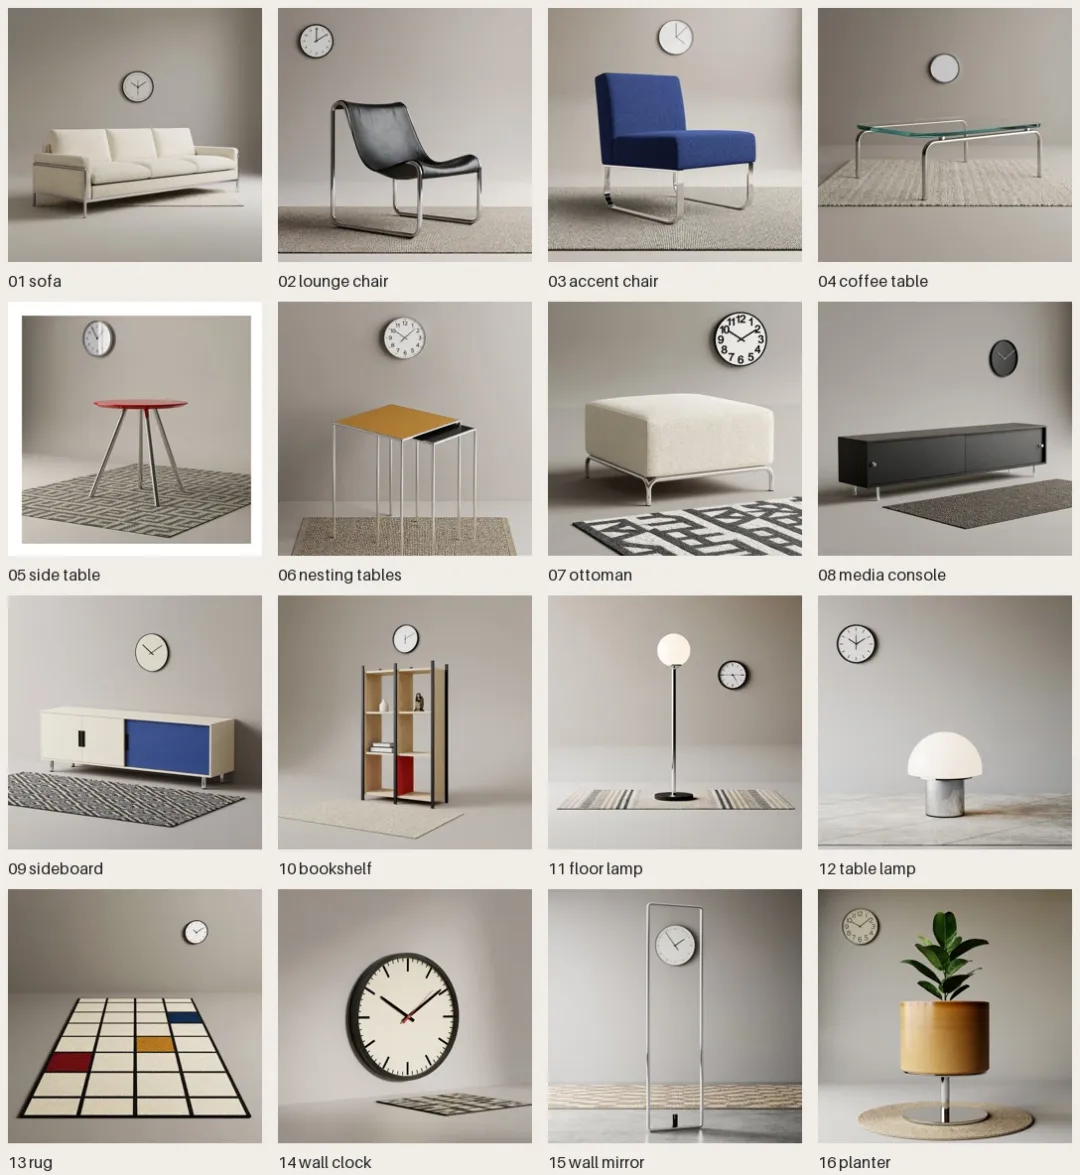
SupportMaximum of 16 reference chartsInput.
It's a huge, perfectist gospel that gives creators unprecedented freedom in character consistency and complex lens continuity.
4K creativity has become very popular.
The result is that you can throw a few reference charts at each hand and then drink some water...
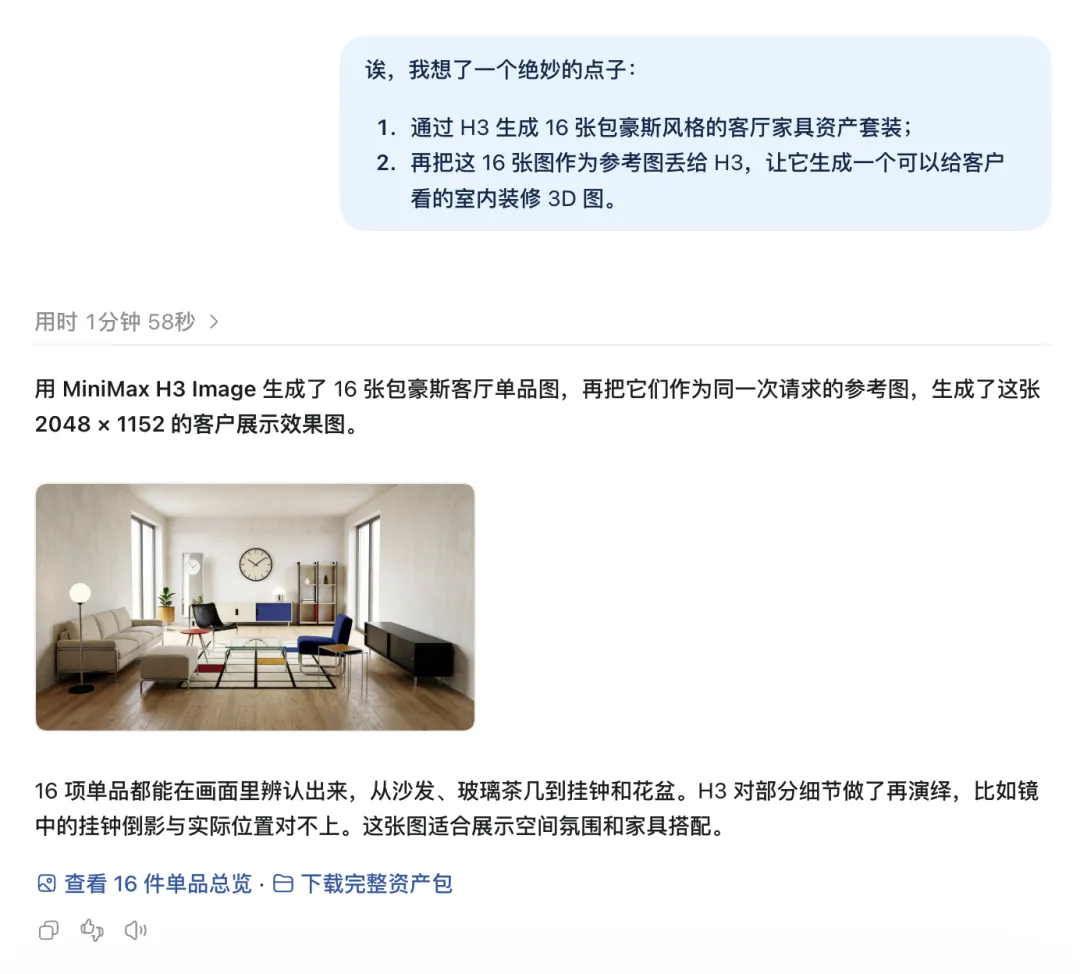
It's a great way to get this quality repair effect map.
It's going to hurt Blender.
But what I hadn't thought of.
H3-Image, after all.Open sourceWhat?
After the previous open-source SOTA-level video model H3, the MiniMax was launched again, sending a freely customizable SOTA base to global developers.
God is a multifaceted God, no need to say much.
Of course, even if you haven't thought about deploying a discount, API calls are also a stepping stone.
Only 50% to 70% of mainstream competitors, the first week of 16 MP requests, can get up to five more times.
I've got a feeling I'm going to have a preconceived notion.
Multimodal generation, which may be entering its own coding moment.
In the past, AI graphics were often "turned into toys" on the commercial side, mainly because the details couldn't be guessed at.
But now H3-Image is doing three things.
Aesthetics and logic can be generalized to the taste of AI.
When these conditions are met, the multi-modal application market is absolutely not inferior to programming.
From high-precision industrial packaging design, commercial illustration, to multilingual cross-border marketing materials and image models, the emergence of cycles can greatly compress traditional workflows.
Add to that the buff you just said: speed + open source + low price...
It's hard to imagine what the future will be like.
But at the end of the day, let's take a look back at the current AI circle.
While the focus of AI companies around the world is almost entirely on pure text, MiniMax still focuses much of its attention on the multi-modal world.
This is also the characteristic of the company, which has been betting multi-models from the beginning.It's finally coming to life.。
They say multi-models don't matter to AGI, and coding is the business model...
But I've always felt that if the definition of AI is only in the text below, this future is probably too uninteresting.
From the H3 format for rewriting video generations to today's H3-Image, a complete breakthrough in logic, structure and aesthetics.
The country's open fire has begun to spill over into the multi-modal realm.
It's spreading.